Claude Code tokens drain fast because every tool call resends the entire conversation so far. A token is the unit a model uses to read and write text, and Claude Code usage is measured in this token volume. The dollar amount you see on a subscription login is not a bill. It is an estimate of what the same volume would cost through the API. The Claude Code cost documentation explains that Claude Code sends the full conversation with every request, and each tool use triggers one more request that carries the tool result (as of October 6, 2026). The numbers below are usage that MCPY measured while running its blog writer automation.
Why Claude Code usage drains so fast
The model has no memory between calls. So every time it calls a tool, such as a search, a page read, or a file save, it bundles the earlier questions, answers, and tool results into a new request. The context window documentation also states that as a conversation goes on, each message and response keeps accumulating in the context window, and earlier turns are preserved as they are. The context window is all the text the model can refer to when it builds an answer. Think of it as the model's working memory.
Thanks to prompt caching, the server reuses the earlier part instead of processing it fresh. The cache read price is 0.1x the base input price for most models such as Sonnet 5.5 (0.05x for Opus 5.5). But it gets cheaper, not gone. The Claude Code documentation notes that even at the cached token rate, in a session left open all day a one-line question still counts as much usage as the whole conversation. The context window documentation likewise explains that a cached prefix still occupies the window. Caching changes what you pay for those tokens, not whether they count toward the window.
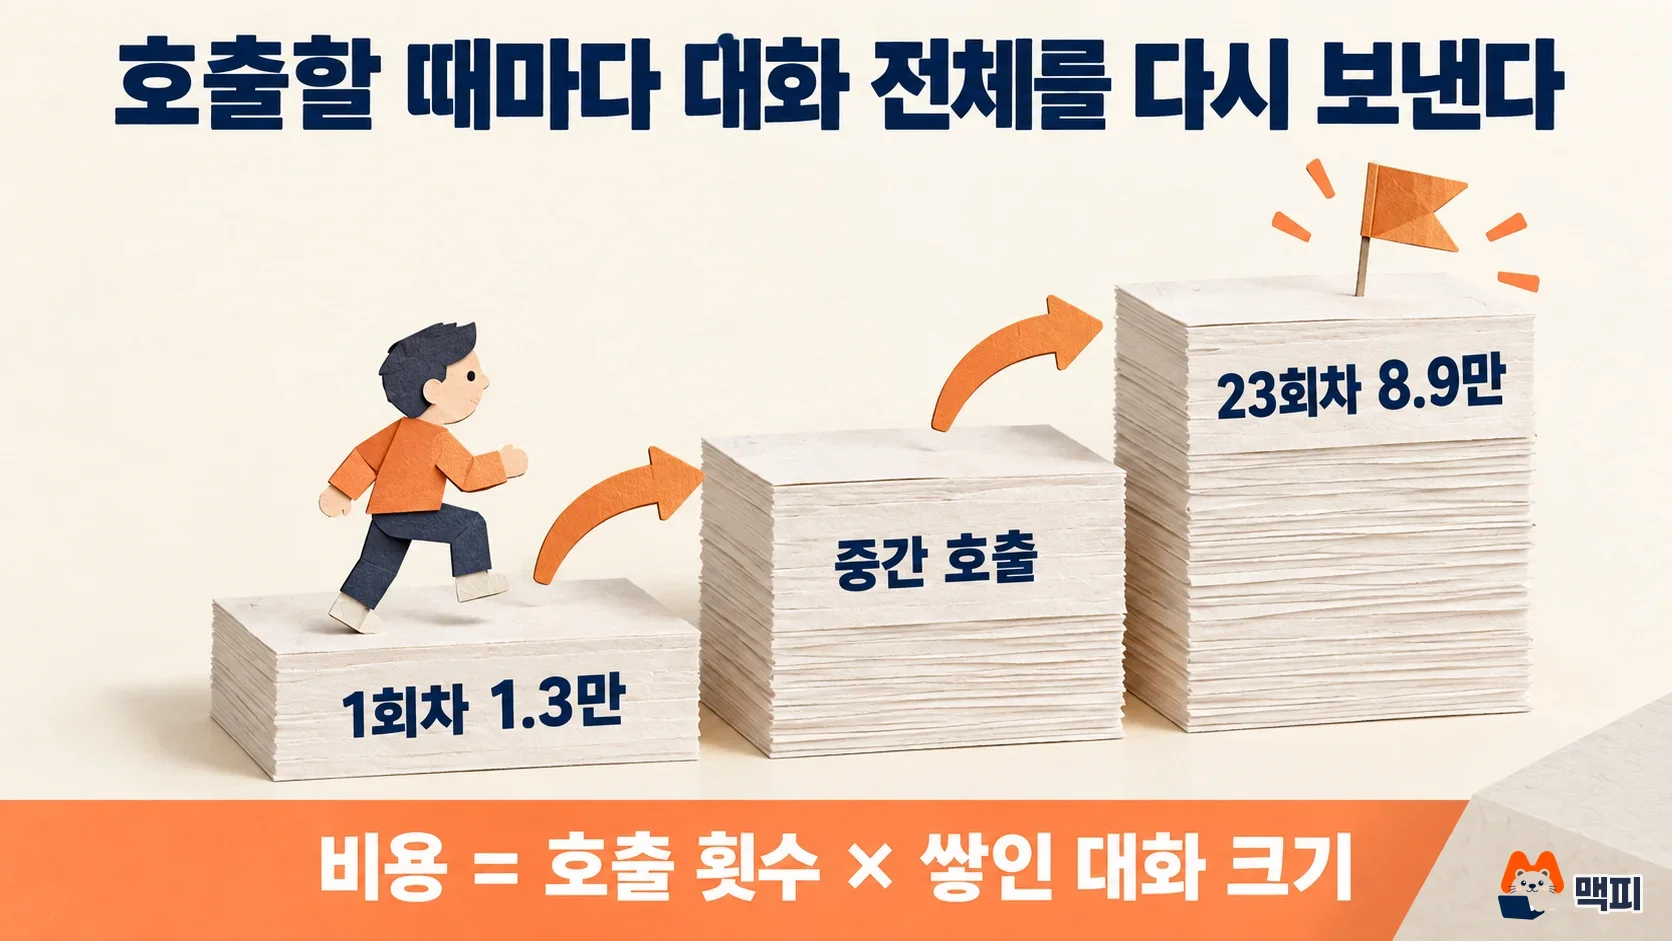
So usage is close to the number of calls multiplied by the size of the conversation built up at that point. The more calls and the larger the accumulated conversation, the heavier each request becomes.
Claude Code token usage measured by MCPY
MCPY runs Claude Code in headless mode (run by command, without a screen) to launch its blog writer every hour. The model is Claude Sonnet 5.5, used through a subscription (Max) login. Over three days, October 3 to 5, the writer ran 103 times, and the API-equivalent amount shown by Claude Code totaled about $243.
Taking one article apart shows the structure. For one article about Copilot, the model was called 23 times. Cache reuse totaled 1.476M tokens. This is the sum added on every call while the accumulated conversation grew from 13K tokens to 89K tokens. Freshly processed input was 80K tokens and output was 21K tokens (3K of it thinking), and the equivalent amount was $1.02. Most of the usage went to rereading the accumulated conversation, not to newly written text.
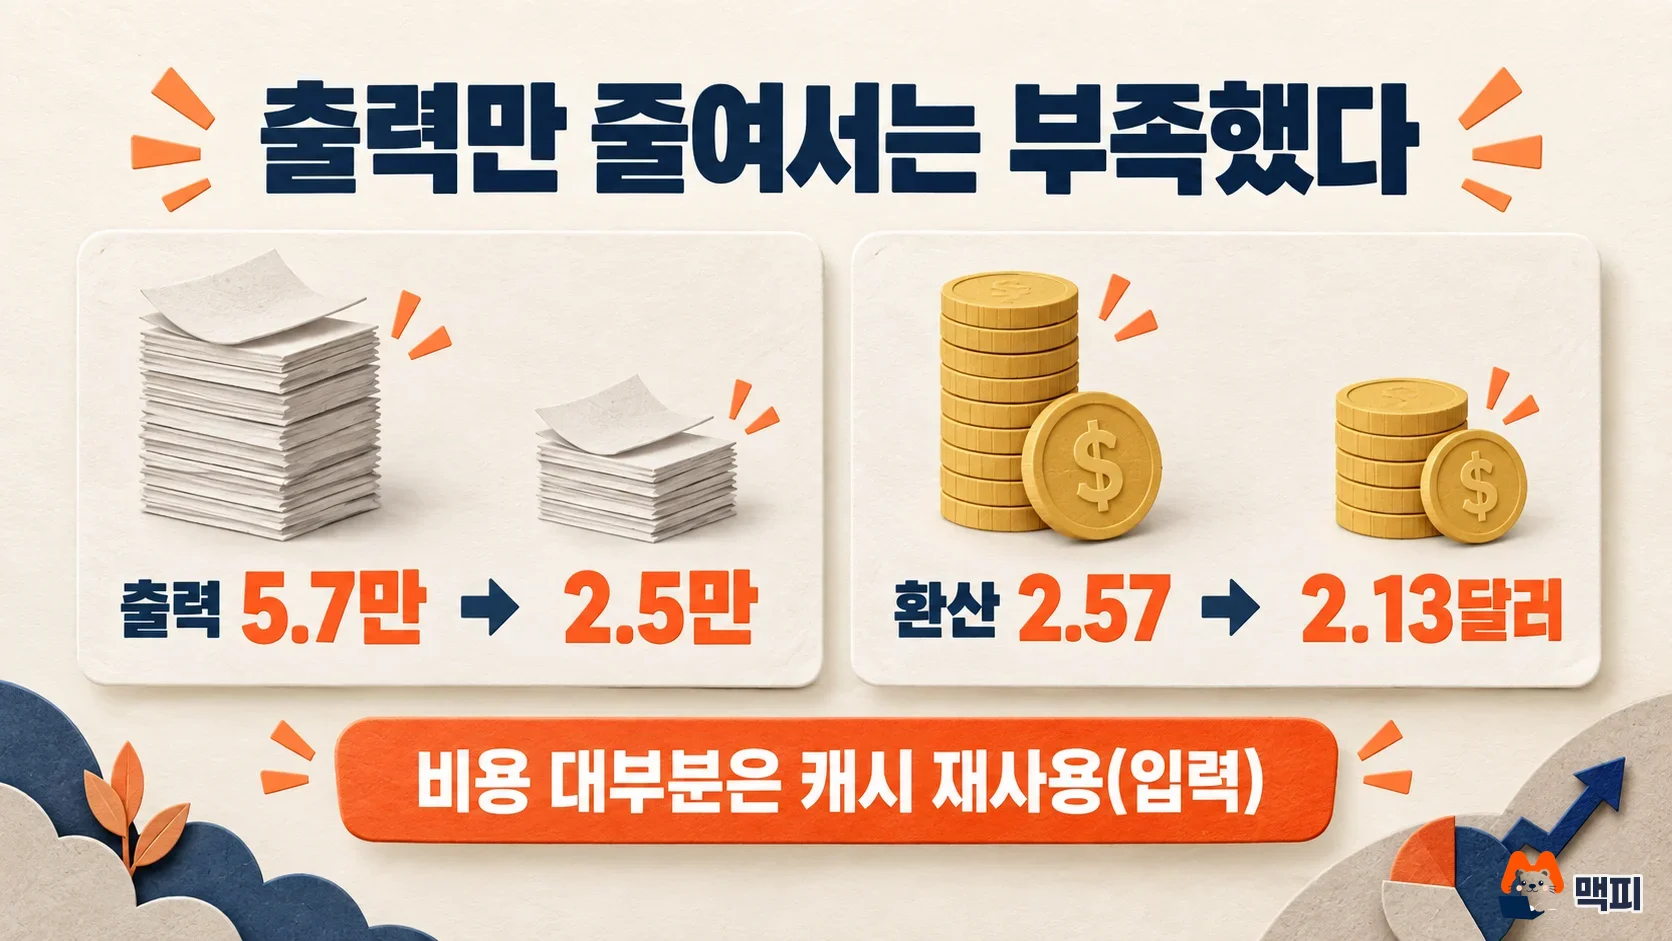
This is why cutting output alone had a small effect. After changing the setup so the body text was no longer rewritten into tool input, output per article fell from 57K to 25K tokens, but the equivalent amount only dropped from $2.57 to $2.13. Most of the cost was cache reuse, which is the input side.
The dollar amount on a subscription login is not a bill
The Session block at the top of the /usage screen in Claude Code shows a dollar amount. According to the official documentation, this amount is an estimate calculated on your own computer by multiplying token counts by list prices. For Pro and Max subscribers, usage is included in the subscription, so this amount has nothing to do with billing. The plan usage bar on the same screen shows how much of your limit is used. MCPY's $243 is likewise not money actually paid. It is the equivalent of the same volume through the API, and it was actually deducted from the subscription usage limit.
There is one exception. If you turn on usage credits to keep working after you pass the subscription limit, usage after that point is handled as credits, and /usage gains a separate row showing credit spend for the month. The Claude Help Center explains that limit consumption varies with conversation length, features, and model, and that claude.ai, Claude Code, and Claude Desktop share the same limit. For exact billing, check the usage page of your account, not the displayed amount. Below is an example Session block from the official documentation.
Total cost:            $0.55
Total duration (API):  6m 20s
Usage by model:
   claude-sonnet-4-6:  1.2k input, 5.3k output, 940.0k cache read, 50.0k cache write ($0.55)
This example, with a few thousand input and output tokens but 940K cache read tokens, shows the same structure. The longer the conversation, the more most of the numbers become cache reads.
How to reduce Claude Code token usage
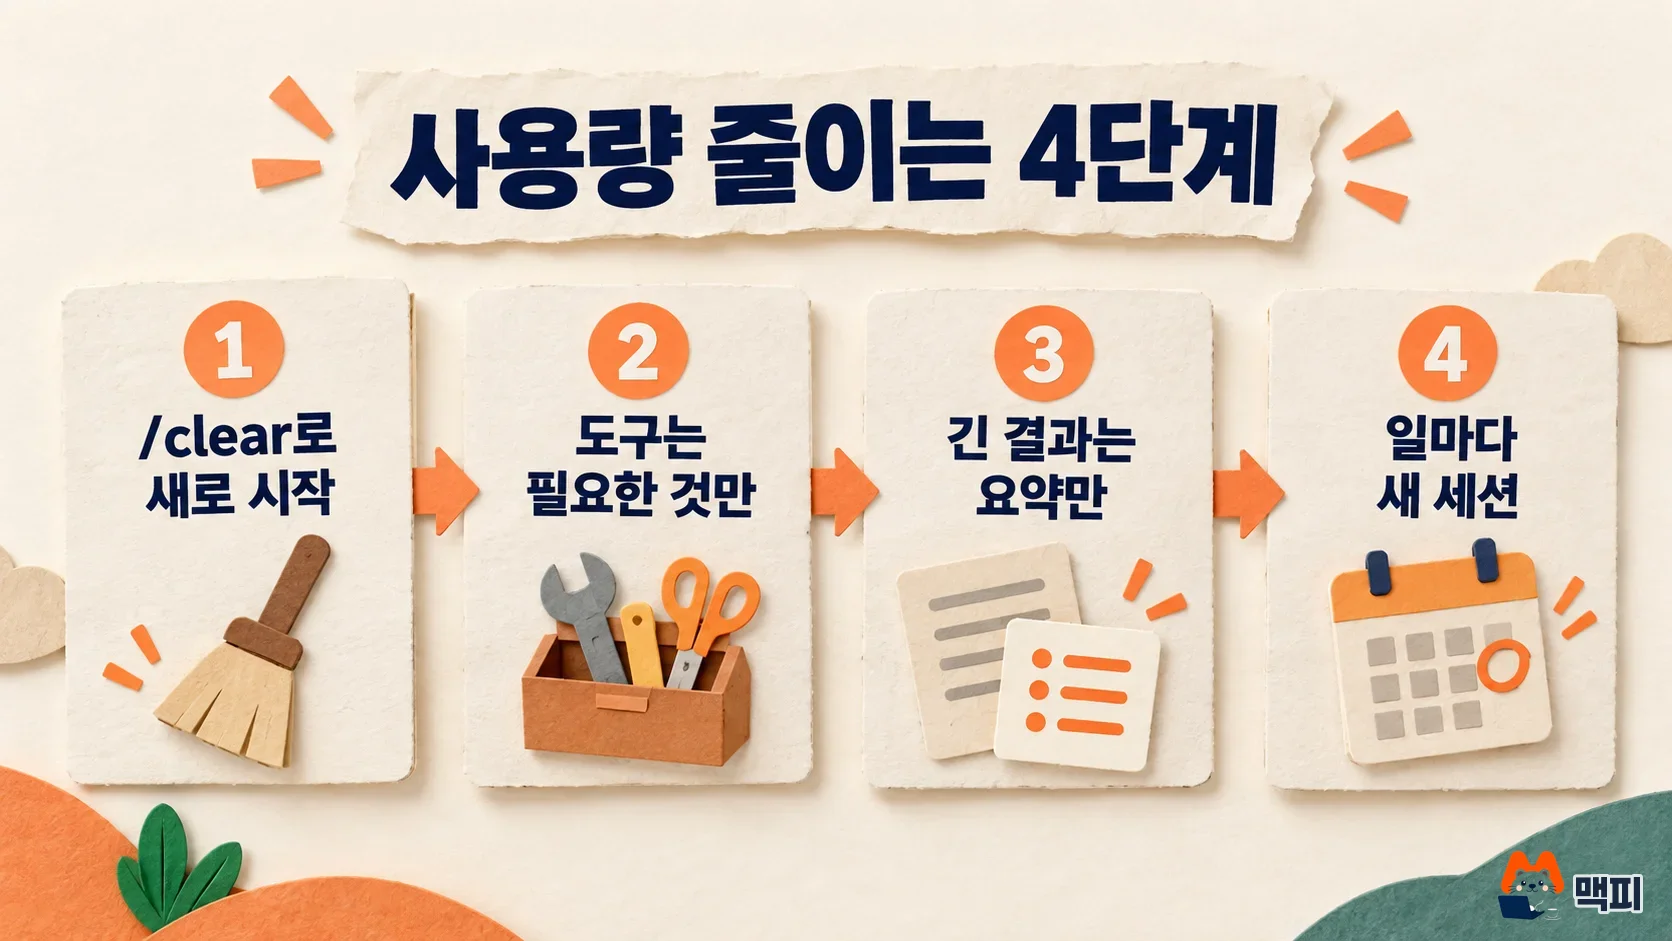
Reducing the accumulated volume worked best. Here are the methods from the official documentation together with the changes MCPY applied to its writer automation.
| Method | How to do it | Source |
|---|---|---|
| Clear the conversation when the task changes | Start fresh with /clear. If you may need to look back at the earlier conversation, name it with /rename first, then clear | Official documentation: stale context wastes tokens on every later message |
| See what has piled up | Use /context to check what takes up space, and turn off unused MCP servers in /mcp | Official documentation: MCP tool definitions are deferred by default, so only names and server instructions are loaded |
| Keep only the tool descriptions you need | In headless runs, connect only the tools that the job uses | MCPY measurement: 102 tool descriptions unrelated to the writer were loaded on every call, and only 23 were kept |
| Shrink tool results | Fetch only the number of search results you need, and get only titles and summaries for duplicate checks. View images as reduced copies | MCPY measurement: related keywords cut from 100 to 20, full text of other articles replaced by title and summary, original images replaced by 900px copies |
| Hand long tasks to a subagent | Delegate output-heavy jobs such as running tests or looking up docs, and only a summary returns to the main conversation | Official documentation: note that a subagent's requests also count toward usage |
| Match model and thinking level to the task | Sonnet is enough for most coding. Lower the level with /effort for simple jobs | Official documentation: Sonnet 5.5 cannot turn thinking off, so adjust it with effort |
| Do not run when there is nothing to do | Run automation only when there is work to process | MCPY measurement: even an empty run with nothing to do used more than 40K tokens |
After applying these changes to the writer, MCPY checked the first article written with the new setup. The maximum accumulated size fell from 210K to 120K tokens, and the average fell from 160K to 95K tokens. The equivalent amount per article fell from $1.89 to $1.43, about 25%, and the article quality review results stayed in the previous range. The $1.02 (one Copilot article), $2.57 to $2.13 (before and after cutting output), and $1.89 to $1.43 (before and after trimming tools and results) are values measured on different articles with different changes, so do not read them as one continuous series.
| Metric | Before | After |
|---|---|---|
| Maximum size | 210K | 120K |
| Average size | 160K | 95K |
Check the effect in /usage. After giving the same task, see whether the cache read tokens in the Session block went down, and compare whether the plan usage bar fills more slowly than before.
Conversations that run for days leak the most
The bigger waste came not from the writer but from long-running conversations. One conversation that a person and Claude had kept going for several days used about 820K tokens of cache reuse on every single reply. Between 1:45 a.m. and 2:50 a.m., the 25 replies in this conversation used 20.33M tokens. That was more than the 12 articles the writer produced in the same period (18.34M tokens).
MCPY's other work sessions looked similar. One orchestrator (a conversation that splits up work and delegates it) that ran for 10 days made 1,847 calls, now carries about 930K tokens per call, and has 970M tokens of cumulative cache reuse. It delegated to subagents 132 times, but the results piled back into this conversation, and auto-compaction ran 4 times. A design conversation that ran for 17 days made 744 calls with 350M tokens cumulative and used no subagents.
Auto-compaction only shrinks the context when it reaches the limit (about 1M tokens). It does not stop the context from filling up again. According to the cost documentation, /compact is also a large request because it reads the whole conversation to summarize it, so compacting a big context is itself a cost. If you do not need continuity, /clear costs nothing. The context window documentation explains that as tokens grow, context rot sets in, with accuracy and recall falling, so choosing what to put in matters as much as how much space you have. A long-running conversation is not only expensive. It also hurts answer quality.
Breaks matter too. The Claude Code cost documentation says the cache lifetime is 1 hour on a subscription, and drops to 5 minutes while you are using usage credits. The first message you send after that time cannot use the cache and reprocesses the full context.
Frequently asked questions
If I hit a limit, can I keep working by switching models with /model?
According to the limit guidance in the Claude Code cost documentation, a "session limit" or "weekly limit" message refers to a usage window shared by all models, so switching with /model does not lift it. Only when the message names a model family, such as "Opus limit" or "Sonnet limit", can you keep working by switching to a different family.
If I log in with an API key, is the displayed dollar amount the bill?
The Session block is a display meant for API users, but it is still an estimate. The official documentation says to check the exact amount on the usage page in the Claude Console.
Does auto-compaction reduce usage on its own?
Compaction is a feature that summarizes the conversation to free up space when the context nears its limit. The conversation builds up again after compaction, and compaction itself is a large request, so the habit of clearing with /clear when the task changes reduces usage more reliably.
The next article covers MCPY's comparison test results: what happened to usage and article quality when research and writing were split across different models for the same job.
Found this useful? Share it
Related posts
Related projects
Get new posts by email
Insights on marketing, analytics, and dev, delivered to your inbox.