The cost of AI blog automation depends less on the writing model and more on how large the conversation grows during research. MCPY tested the same topic. GPT-6.1 Sol did the research and produced an evidence bundle (46 lines). Claude Sonnet 5.5 then wrote the post in one pass with no tools. In that writing step, Claude used 1 call, 23K input tokens, 5.5K output tokens, and 36 seconds. When Sonnet researched and wrote on its own, input was 121K tokens. A token is the unit a model uses to process text. Input is what you send to the model, and output is what the model writes back. These numbers were measured while running the MCPY blog writer from October 3 to 6, 2026, with October 6 as the reference date.
Why tokens pile up in AI blog automation
A model has no memory between calls. Every time it uses a tool, such as a search or a page read, the whole conversation so far is sent again. The Claude Code cost documentation also explains that every request carries the full conversation and that each tool use adds one more request. So cost is close to the number of calls multiplied by the conversation size at that point.
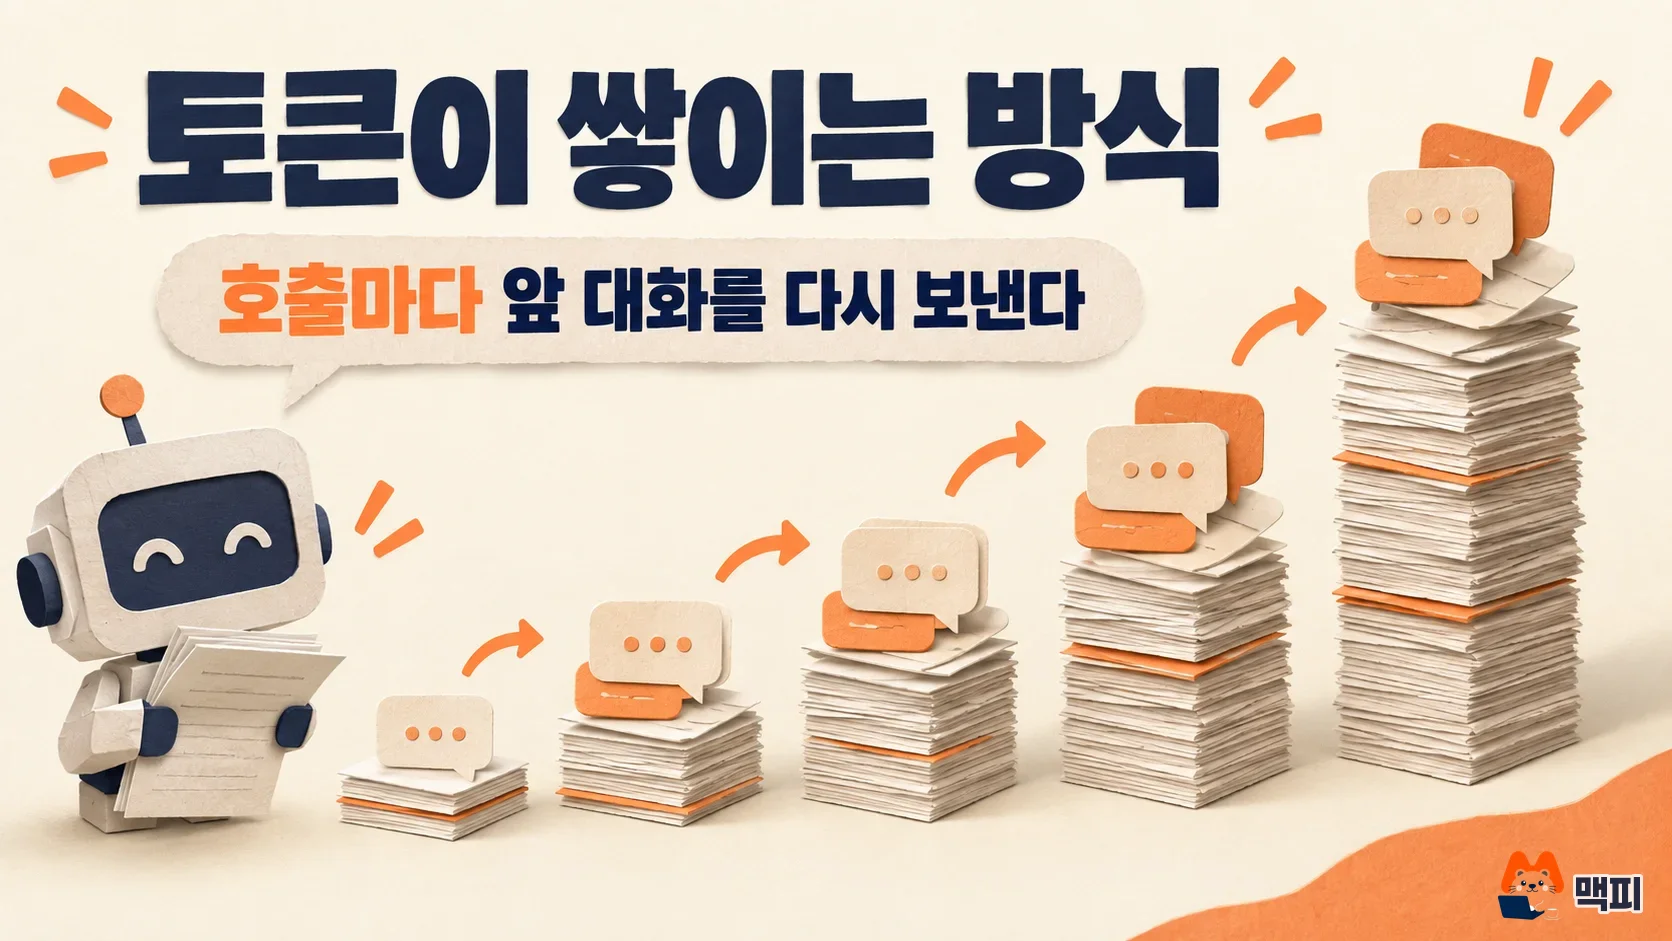
The resent early part is read from a cache the server stores (reuse of earlier processing results), so it is cheaper. The Anthropic prompt caching documentation lists cache reads at 0.1x the base input price. The OpenAI prompt caching documentation lists cached input for GPT-6.1 Sol at 0.05x. Cheap does not mean free, though. In MCPY's measurements, one post made 23 model calls. Cache reuse totaled 1.476M tokens, and newly processed input was 80K tokens.
That is why cutting output alone has limits. Stopping the body text from being rewritten into tools cut output from 57K to 25K tokens per post. The converted cost fell only slightly, from $2.57 to $2.13. Most of the cost sat in cache reuse, which is the input side.
How much quality and tokens change when you split research and writing
MCPY tested three approaches. The models were Claude Sonnet 5.5, gpt-6.1-sol, gpt-5.6-terra, and gpt-6-luna. Judging combined a blind human comparison with MCPY's own quality score (style and facts). Test 1 gave every model the same evidence and asked only for writing. In Test 2, each model did web research first (the topic was Looker Studio). Test 3 split research and writing.
| Test | Method | Tokens and time | Human verdict |
|---|---|---|---|
| Test 1 | Writing only, same evidence (Sonnet 5.5, gpt-6.1-sol, gpt-5.6-terra, gpt-6-luna) | Own quality score, style: Sonnet 0.73, sol 0.71, terra 0.61, luna 0.60. Fact scores were similar at 0.87 to 0.89 | Sonnet > terra = sol >> luna |
| Test 2 | Sonnet researches and writes on its own | 12 turns, 7 links, input 121K, output 6.6K, 80 seconds | sol ahead |
| Test 2 | sol researches and writes on its own | 16 web searches, 14 links, input 399K (cache 339K), output 3.4K, 173 seconds | sol ahead |
| Test 3 | sol builds a 46-line evidence bundle, then Sonnet writes in one pass with no tools (writing step) | Input 23K, output 5.5K, 36 seconds, 1 call | This method and sol alone were best |
In Test 1, Sonnet led on both style and the human verdict, and fact scores barely differed between models. In Test 2, the verdict flipped to sol because of research depth, not writing skill. sol collected 14 links and Sonnet collected 7. Test 3 combines the two strengths. The human verdict said the post was more detailed, but it also pointed out that the official terms were hard to follow. This was a small test on one topic, so the same result may not hold for every topic. The Test 3 numbers cover the writing step only. The tokens sol used during research are not in this table. So we cannot claim that total cost fell. We can only say that the conversation on the writing side got shorter.
How to split research and writing in AI writing
The key is to keep the research conversation out of the writing conversation. The research model organizes official links and facts into an evidence bundle. The writing model receives only that bundle and writes in one pass in a fresh conversation. No search tool is attached on the writing side, so it finishes in 1 call and no conversation builds up.
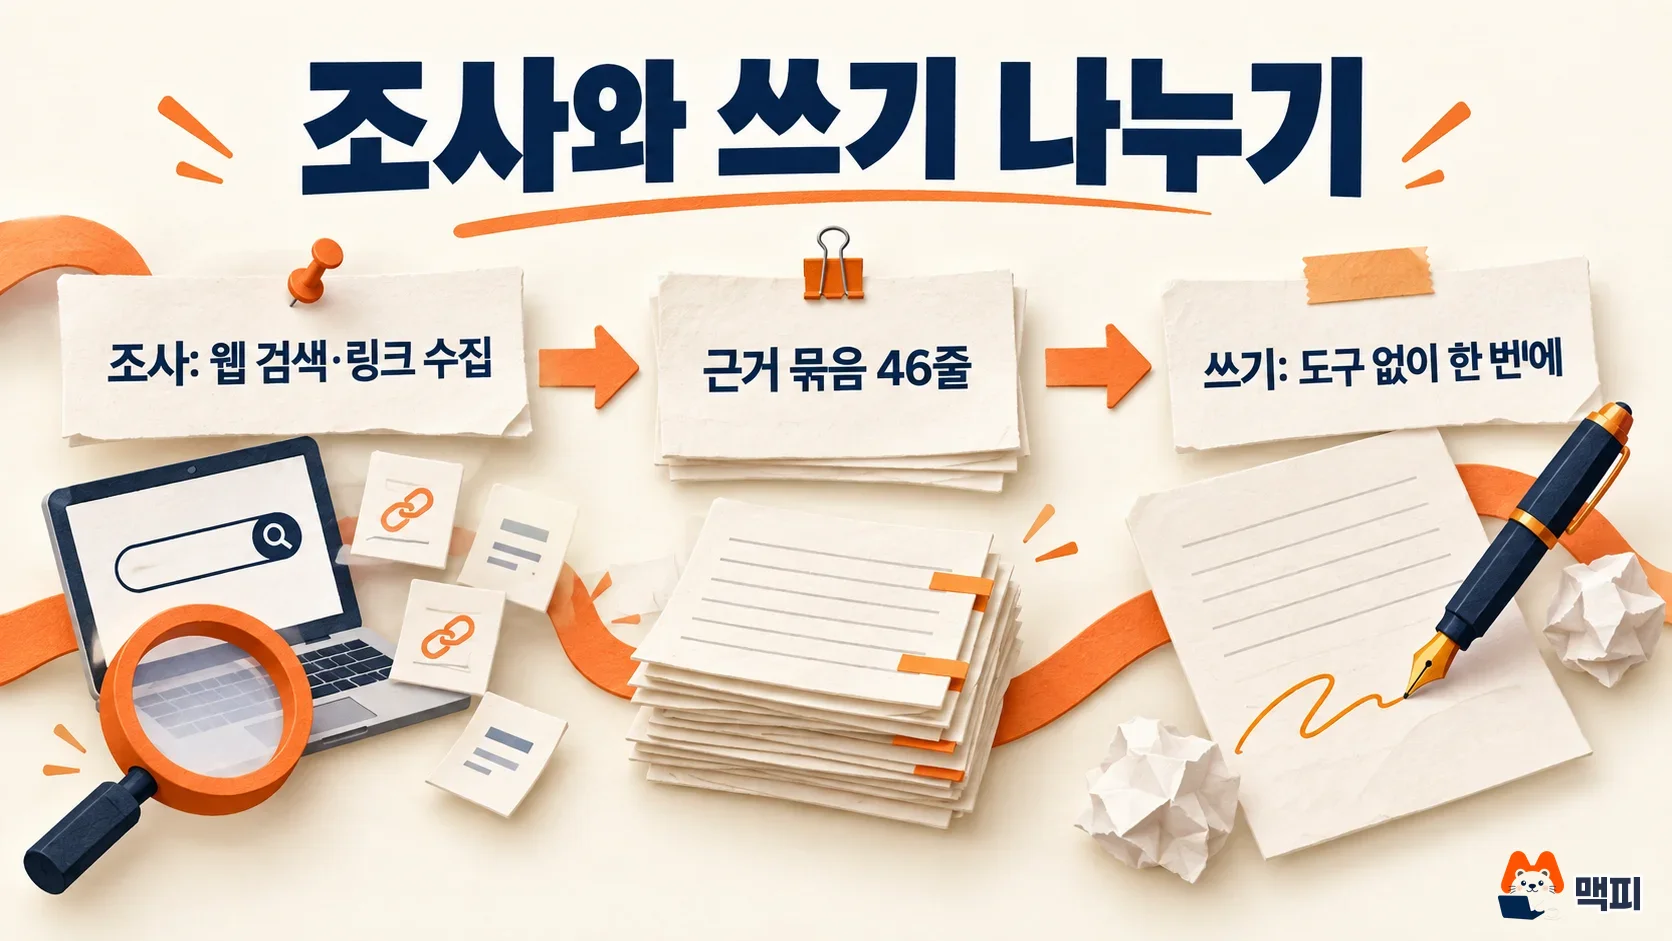
- Give the research model the topic and the reader's questions. Ask it to build an evidence bundle with an official link attached to each fact. The bundle in the MCPY test was 46 lines.
- Give the writing model only the evidence bundle, the style rules, and the output format. Attach no tools.
- Receive the result as a file and pass it to the rule check. Output also shrinks when the body text is not rewritten into tool input.
The weak point in the Test 3 review was hard official terms. You can reduce it by adding "explain each official term in one line the first time it appears" to the writing instructions. MCPY has not tested this fix yet.
Removing unneeded material from the conversation before splitting also helped. MCPY cut the tool manuals unrelated to the writer from 102 to 23. It cut the related searches in search volume lookups from 100 to 20. It replaced full-size image checks with 900px reduced copies. As a result, the peak size that builds up fell from 210K to 120K tokens. The converted cost per post fell about 25%, from $1.89 to $1.43. The own quality score stayed within its earlier range (style 0.77, facts 0.85). This runs on a subscription login, so these amounts are not actually billed. According to the Claude Code cost documentation, the dollar value on screen is an estimate that prices the token count at list price.
Be careful with multi-agent setups, where several AIs split the roles, because they can cost even more. Anthropic's article on its multi-agent research system states that agents use about 4x the tokens of a normal chat, and multi-agent systems use about 15x. The gain from splitting does not come from adding agents. It comes from cutting the writing step's conversation short. If you want to know about usage limits themselves, start with our guide to Claude Code installation, pricing, and usage limits.
Use GPT for research and Claude for writing
In MCPY's tests, Sonnet 5.5 led on prose and the human verdict, and gpt-6.1-sol led on research depth. So we recommend sol for research and Sonnet for writing. This advice rests on a test of one topic, so if your topic changes, it is safer to run the same comparison again.
On price, the two models are close. On the OpenAI model page, GPT-6.1 Sol costs $2 per 1M input tokens, $0.1 for cached input, and $10 for output. Its context window (the maximum length it can read at once) is 1.05M tokens. On the Anthropic pricing page, Claude Sonnet 5.5 also costs $2 for input, $0.20 for cache reads, and $10 for output (see our Claude Sonnet 5.5 API guide for more features). Input and output prices are the same, so the difference comes from the number of calls and the size of the conversation that builds up.
Where to check whether your automation leaks tokens
If you use Claude Code, run /usage in a session and look at the token usage in the Session block. According to the Claude Code cost documentation, this block shows input, output, cache read, and cache write tokens by model. If cache reads are several times larger than input, the conversation has been building up for a long time. In Claude Code v2.1.251 and later, the Prompt cache (main) line in the same block also shows the cache hit rate.
After splitting, run both methods once on the same topic. Compare whether the writing step's call count and input tokens went down. If calls are close to 1 and input is smaller than in the method that includes research, the split is working. Then check that the post passes the quality check, to confirm the post did not get shallower as it got cheaper.
Frequently asked questions
Do subagents (helper AIs that handle one assigned task) reduce tokens?
Only a summary returns to the main conversation, so less builds up there, but the subagent's requests still count toward usage. The Claude Code cost documentation recommends keeping long output inside the subagent and receiving only the summary. It also states that a subagent's requests use usage separately.
Why does a dollar amount appear when I use a subscription?
It is an estimate that Claude Code calculates by pricing the token count at list price. The same document explains that for Max and Pro subscribers, usage is included in the subscription and the figure has no meaning for billing. Treat it as a rough gauge of how much is deducted from your subscription limit.
Found this useful? Share it
Latest posts
Kakao Share Thumbnail Not Showing? Here's the Fix (JavaScript SDK 2025)
Learn why Kakao Share thumbnails don't appear even with a valid imageUrl, and fix it using scrapImage to convert your URL into a KAGE CDN URL. Step-by-step guide.
How to Generate CRM User Manuals in 20 Minutes with Claude Code Sub-Agents
Learn how Claude Code sub-agents can analyze your CRM codebase and auto-generate user manuals and visual guidebooks in just 20 minutes. See the real-world results.
GEO Generative Engine Optimization: The Complete 2025 AI Marketing Strategy Guide
Learn what GEO (Generative Engine Optimization) is, how it differs from traditional SEO, and discover 5 proven AI marketing strategies to get cited by AI search engines in 2025.
Related projects
Get new posts by email
Insights on marketing, analytics, and dev, delivered to your inbox.