GPT-6 Astra's Ultrafast is a paid speed option that turns on when you set service_tier to ultrafast in an API request. The price is 6 times standard: $60 per 1 million input tokens and $300 per 1 million output tokens (as of September 30, 2026). At an assumed 1,400 KRW per dollar, 1 million input tokens cost 84,000 KRW and 1 million output tokens cost 420,000 KRW. Processing is available only in the US and globally, so you cannot use it on regional endpoints such as the EU.
The official sources are the OpenAI developer docs, the Ultrafast mode guide and the API pricing page. We read both directly on September 30, 2026. The speed multipliers (up to 8x for Codex, up to 6x for the API) were announced by OpenAI at DevDay on September 29, and we confirmed them in the DevDay 2026 announcement post. The same post says "Astra is available now and Sol is coming soon." It applies from the announcement date, September 29. MCPY has not measured the actual speedup ourselves. The KRW values below are examples calculated from an assumed exchange rate.
Three lines to start with
- How to enable it: set
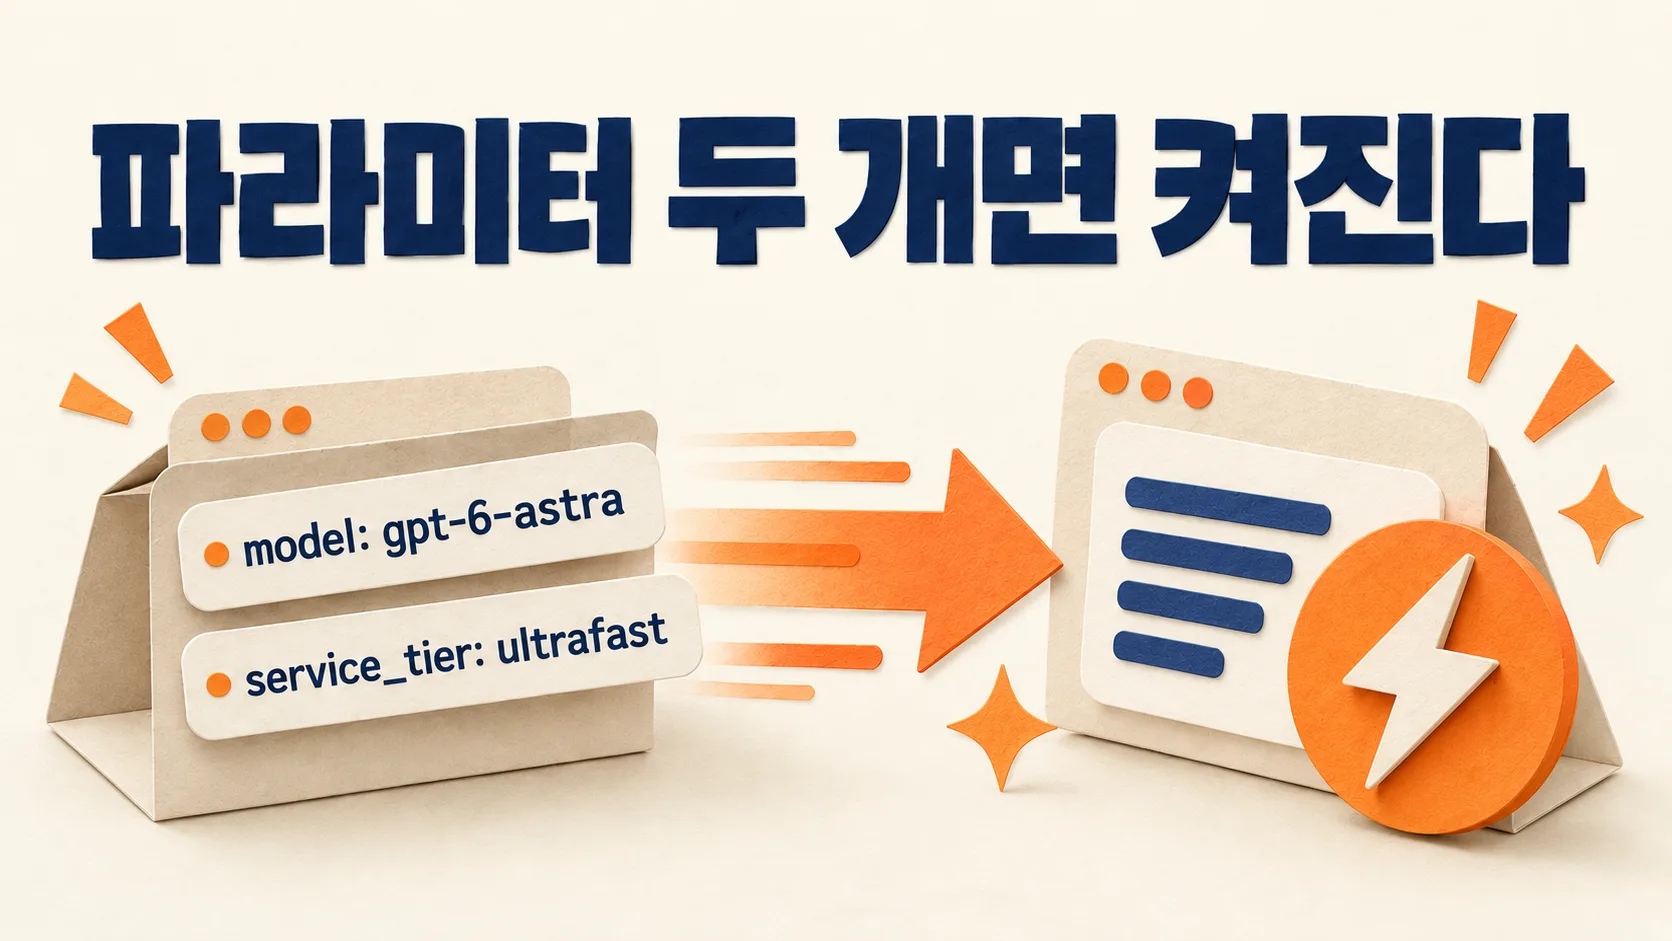
modeltogpt-6-astraandservice_tiertoultrafastin the request. The docs strongly recommend a WebSocket connection. - Price: $60 input, $6 cached input, $300 output (per 1 million tokens). If the input exceeds 272,000 tokens, it is $120 for input and $450 for output.
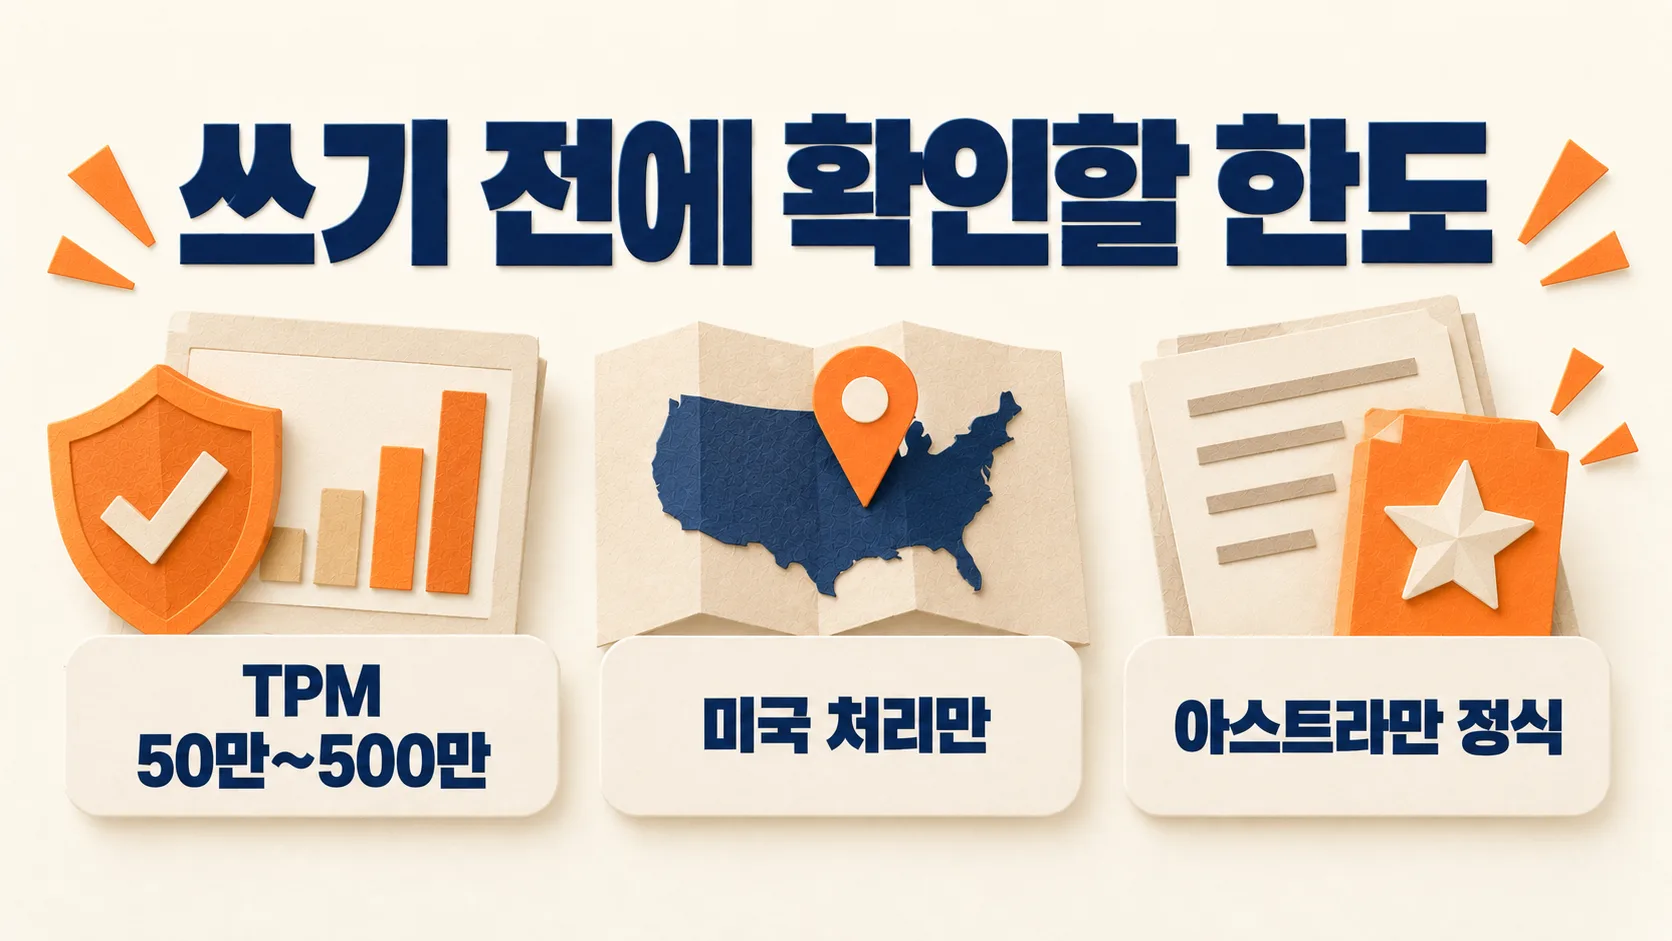
- Limits: tokens per minute are 500,000 for Tiers 1 to 3, 1 million for Tier 4, and 5 million for Tier 5. Only US data residency and global processing are supported.
Ultrafast is a service tier, and it works on limited models
Ultrafast is not a new model. It is a service tier that runs the same model faster. The OpenAI API lets you pick the processing mode per request with the service_tier value. Ultrafast is one of those values, and OpenAI calls it a paid speed tier. You buy speed and pay a higher unit price.
The docs list GPT-6 Astra (generally available) and GPT-5.6 Sol (preview access only) as supported models. So GPT-6 Astra is the only model anyone can enable it on today. The announcement post only says Sol is coming soon and gives no date. MCPY treats the date Ultrafast opens on Sol as undecided. We covered the standard price of GPT-6.1 Sol separately in GPT-6.1 Sol price and Astra comparison.
The API usage is two parameters
The values to change are the same for HTTP requests and WebSocket. For HTTP, the docs say to put gpt-6-astra in model and ultrafast in service_tier on every request. The HTTP body below is an example MCPY built in the Responses API format. We have not called it ourselves.
POST https://api.openai.com/v1/responses
{
  "model": "gpt-6-astra",
  "service_tier": "ultrafast",
  "input": "이 상품 설명을 세 줄로 요약해 줘"
}
The docs include a WebSocket example as is. You open the connection once and keep sending response.create events. To continue an earlier response, add previous_response_id.
connection.response.create(
    model="gpt-6-astra",
    service_tier="ultrafast",
    previous_response_id=previous_response_id,
    input=prompt,
)
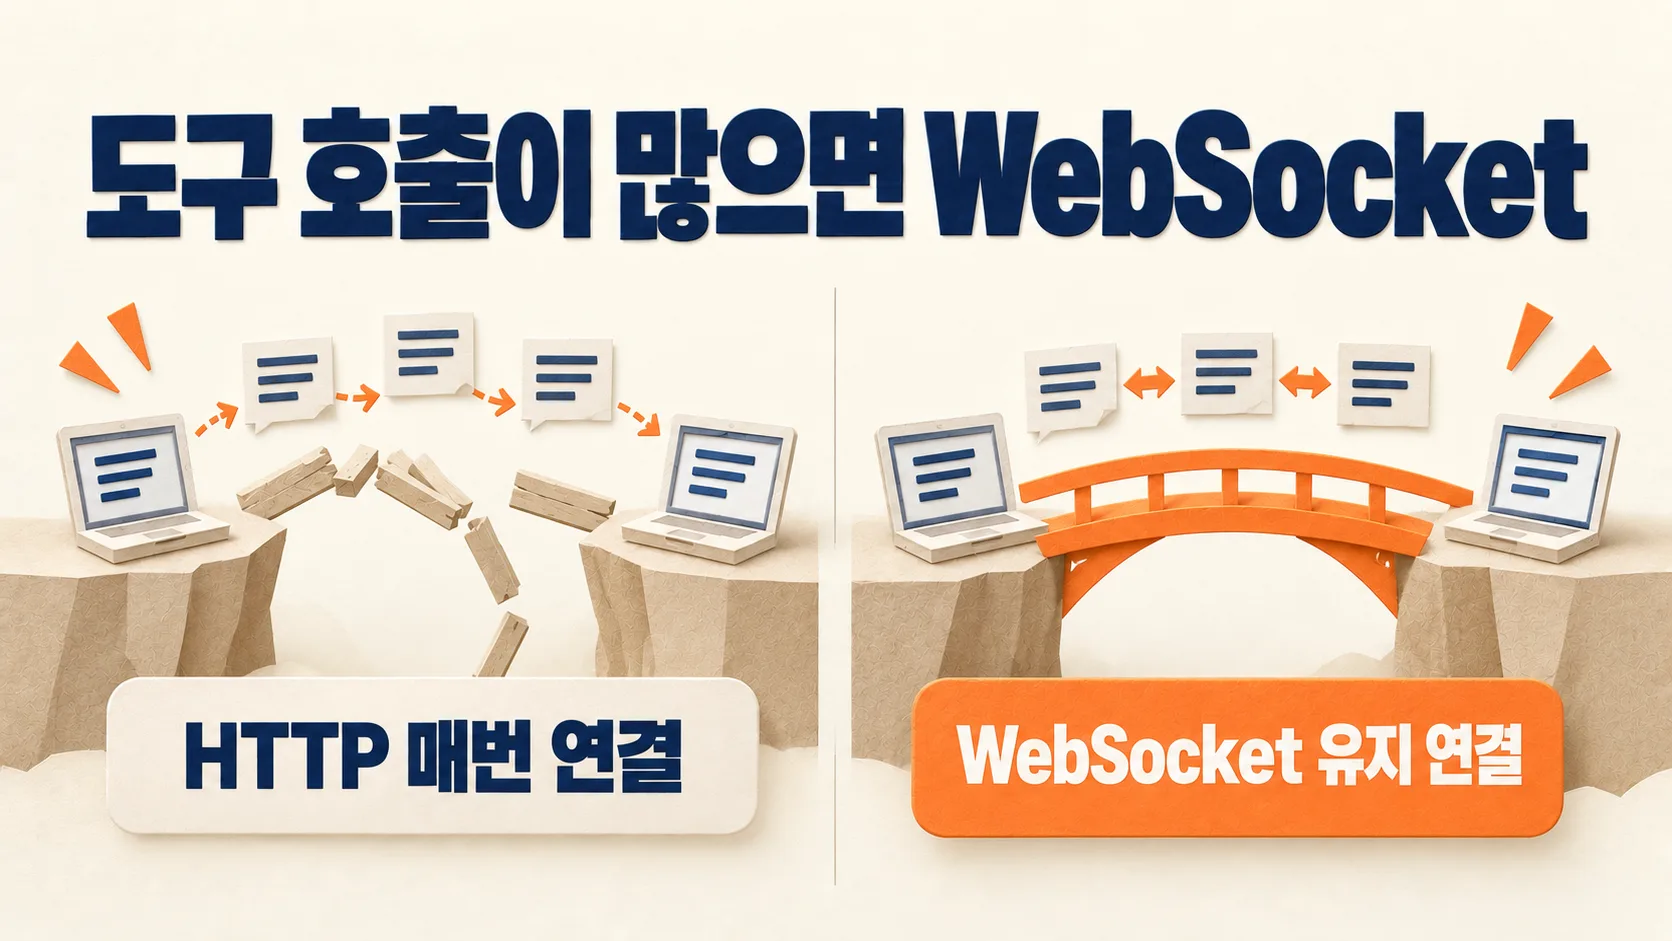
Why recommend WebSocket? An agent calls a tool, gets the result, and calls the model again, many times in short intervals. If you open a new connection for every request, connection time is added each time and eats the gain from the faster model. The docs also say that without a persistent connection, network overhead can reduce the latency gain (Ultrafast mode guide). For a simple single question and single answer, HTTP is enough.
Pricing per request is easy to calculate
The gpt-6-astra entry on the pricing page is as follows. Units are dollars per 1 million tokens. A token is the unit in which the model reads and writes text.
| Tier | Input | Cached input | Output |
|---|---|---|---|
| Standard | $10 | $1 | $50 |
| Ultrafast (272,000 tokens or less) | $60 | $6 | $300 |
| Ultrafast (over 272,000 tokens) | $120 | $12 | $450 |
The pricing page also lists cache write fees ($75 for short requests, $150 for long requests). We could not confirm in the docs which requests incur this fee, so we left it out of the calculation below. For reference, the input prices on the page run $5 for Batch and Flex, $20 for fast mode, and $60 for Ultrafast.
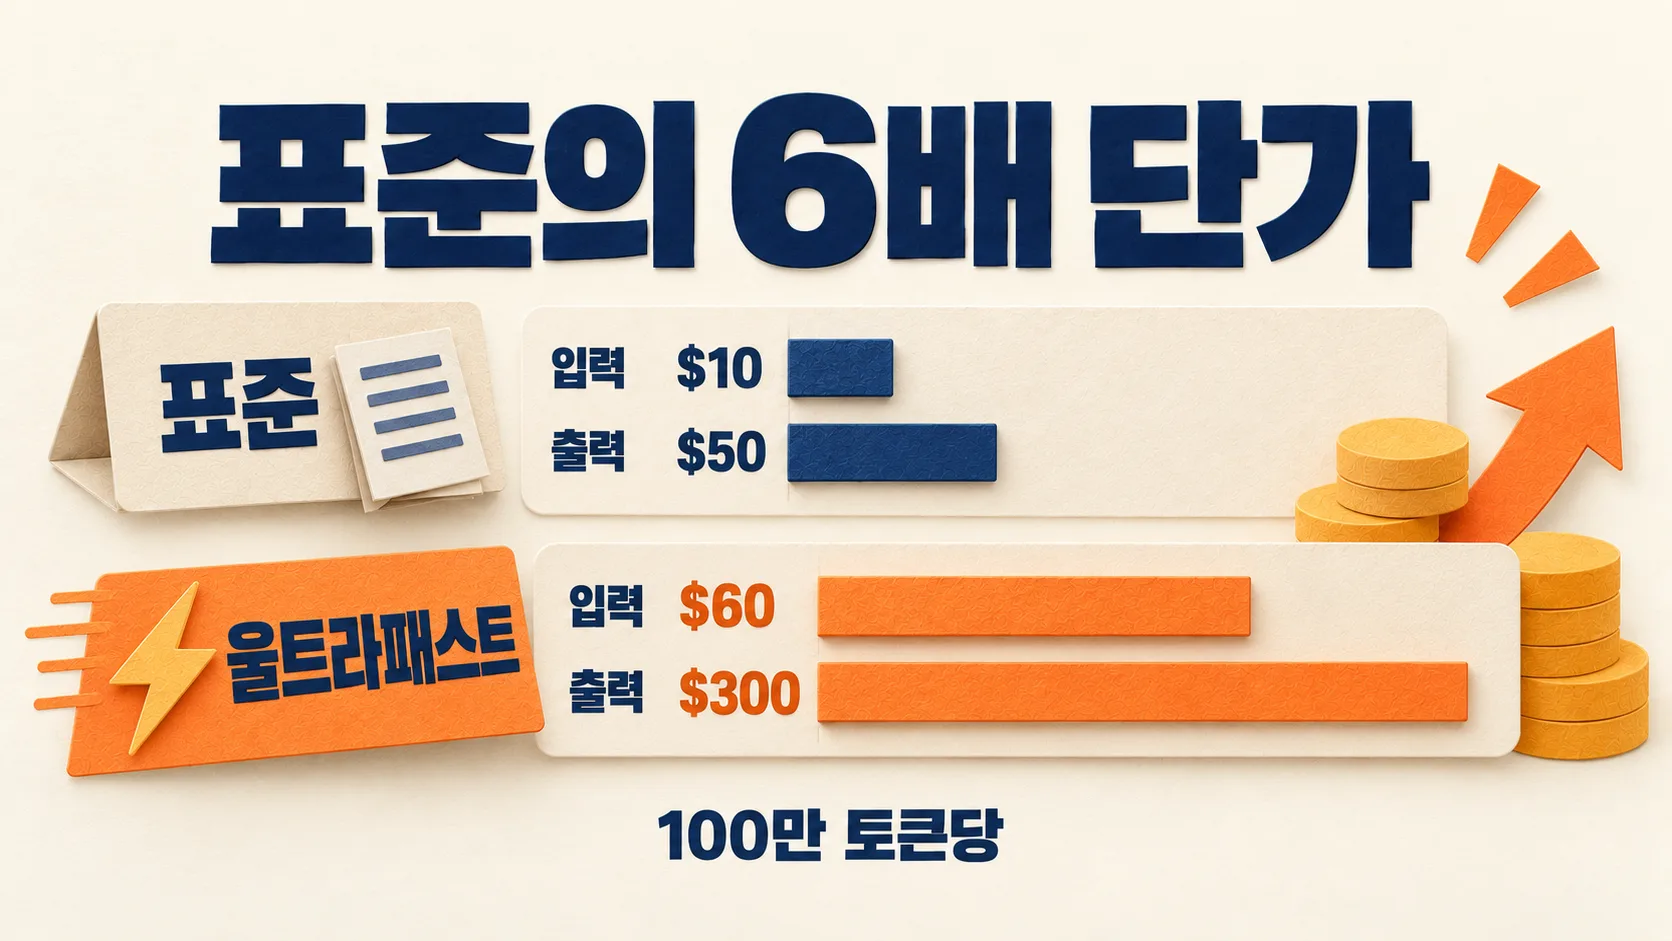
Let's calculate one request: 10,000 input tokens and 2,000 output tokens (no cache).
| Tier | Calculation (unit price per 1 million tokens) | USD | KRW (1,400 KRW per dollar) |
|---|---|---|---|
| Standard | 10,000×10 + 2,000×50 | $0.20 | 280 KRW |
| Ultrafast | 10,000×60 + 2,000×300 | $1.20 | 1,680 KRW |
At 1,000 requests a day, that is 280,000 KRW for standard and 1,680,000 KRW for Ultrafast. If the up to 6x stated by OpenAI holds, model generation time drops to as little as one sixth, but the cost goes up 6 times. MCPY sees two places where this trade makes sense. One is requests where a person waits at the screen for the answer. The other is long chained agent tasks where each step needs the previous result. Bulk classification or summarization that runs overnight fits standard or Batch.
The limits and constraints are three
The docs state three constraints. The first is the tokens-per-minute limit (TPM). It is 500,000 for Tiers 1 to 3, 1 million for Tier 4, and 5 million for Tier 5. The docs table does not say how input and output are counted together. If we assume the total of input and output, at 12,000 tokens per request, Tiers 1 to 3 cap out at about 41 requests per minute.
The second is processing location. The docs say only US data residency and global processing are supported, and regional processing endpoints outside the US, such as the EU, are not. The third is the model. Only GPT-6 Astra is generally supported. Streaming is supported.
What to check when using it from Korea
- KRW amounts: prices are published in dollars only. Your actual bill depends on your card exchange rate, fees, and VAT handling. Check business registration and VAT settings on the OpenAI billing settings page.
- Data processing location: the docs list no Korea region, only US and global processing. If your service handles customer personal data, first review cross-border transfer consent and outsourcing terms under Korean privacy rules.
- ChatGPT plans and the API are separate: according to the announcement post, in ChatGPT the Pro 500 plan includes Ultrafast access, while the API is billed separately at the token prices above.
Common mistakes
The most common mistake is reading a 6x price as a 6x faster response. What OpenAI stated is up to 6x in the API, and only the speed at which the model produces its answer improves. Network time and your own server time stay the same. Second, changing only the model name and leaving out service_tier. This falls back to the standard price and is not faster. Third, sending long inputs carelessly. Above 272,000 tokens, the whole request is billed at $120 for input and $450 for output. Fourth, mistaking a rate limit for an outage. Tiers 1 to 3 get 500,000 tokens per minute, so bulk calls get blocked quickly. Fifth, sending every request as Ultrafast. If you send work that no user is waiting on, your bill becomes 6 times larger.
Test in this order before you pay
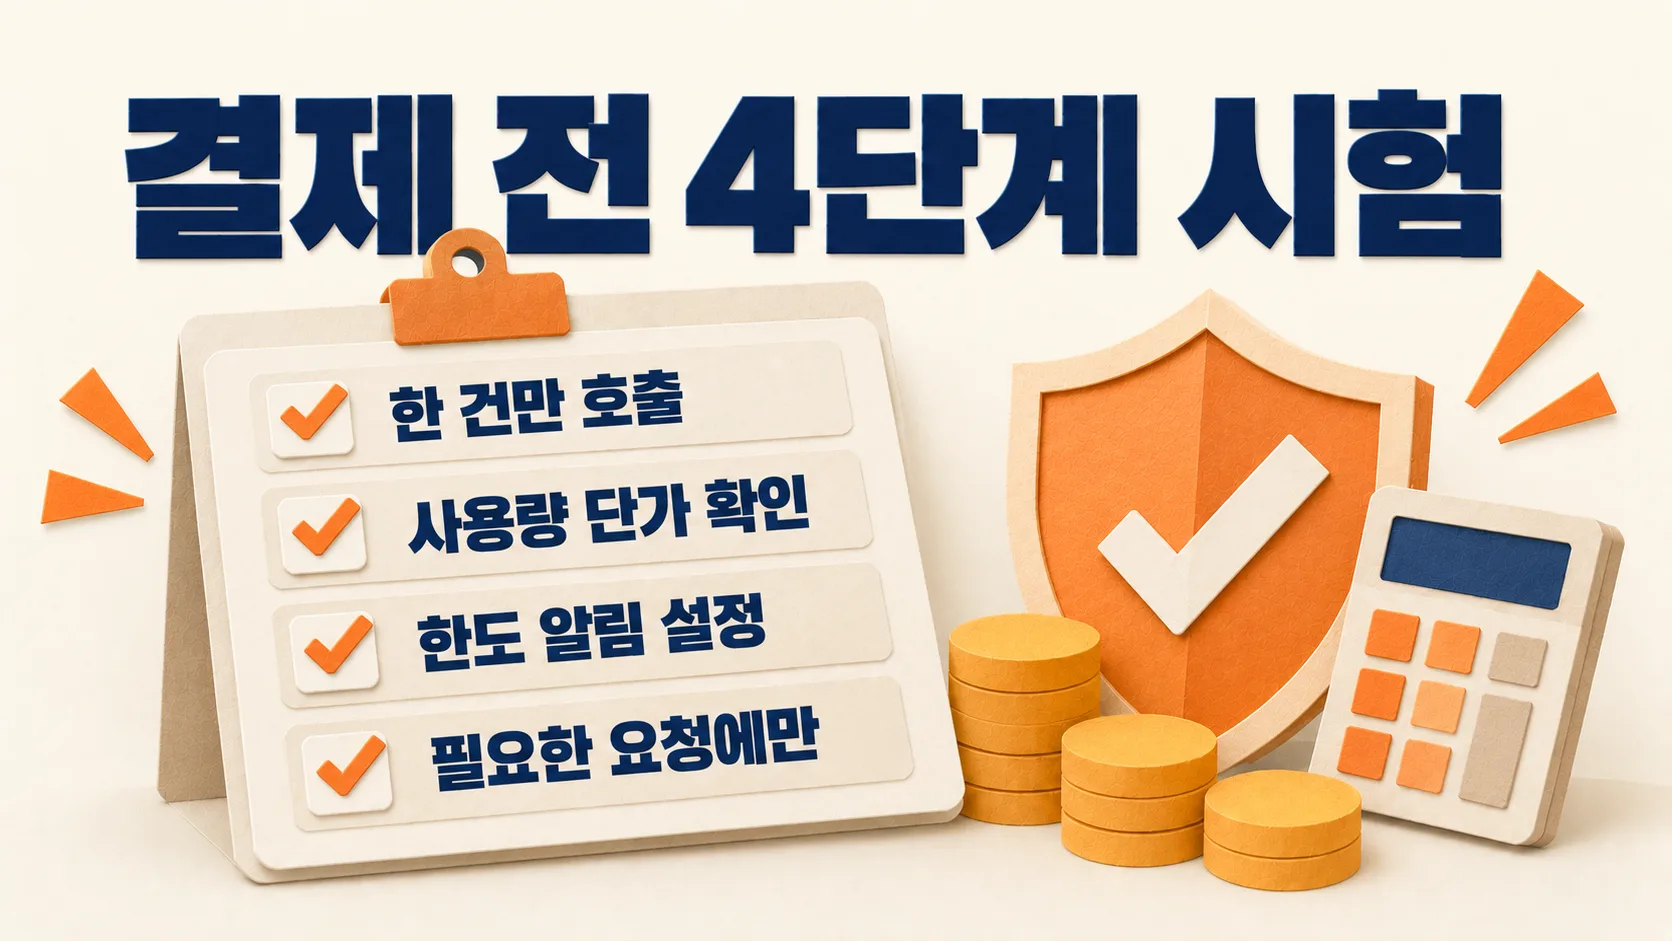
- Call once with
service_tierset toultrafaston a single request. One short input is enough. - On the OpenAI usage screen, check that the input and output unit prices for that request match the pricing page ($60 input, $300 output).
- Set a monthly usage limit and alerts on the project. Even if a loop calls the API by mistake, the bill will not keep growing.
- Run the same request five times on standard and five times on Ultrafast, and measure the response time difference yourself. Turn it on only for requests where that difference is worth 6 times the price.
Prices and limits may change because this was just announced. Open the OpenAI pricing page once more to confirm the unit prices before you turn it on.
Sources
- OpenAI developer docs, Ultrafast mode (checked directly on September 30, 2026)
- OpenAI developer docs, API pricing (checked directly on September 30, 2026)
- OpenAI developer community, DevDay 2026 announcements and developer resources (September 29, 2026)
Found this useful? Share it
Latest posts
Kakao Share Thumbnail Not Showing? Here's the Fix (JavaScript SDK 2025)
Learn why Kakao Share thumbnails don't appear even with a valid imageUrl, and fix it using scrapImage to convert your URL into a KAGE CDN URL. Step-by-step guide.
How to Generate CRM User Manuals in 20 Minutes with Claude Code Sub-Agents
Learn how Claude Code sub-agents can analyze your CRM codebase and auto-generate user manuals and visual guidebooks in just 20 minutes. See the real-world results.
GEO Generative Engine Optimization: The Complete 2025 AI Marketing Strategy Guide
Learn what GEO (Generative Engine Optimization) is, how it differs from traditional SEO, and discover 5 proven AI marketing strategies to get cited by AI search engines in 2025.
Related projects
Get new posts by email
Insights on marketing, analytics, and dev, delivered to your inbox.