Meta's commercial terms include a clause from October 30 that authorizes crawling of advertiser websites. Crawling means a bot automatically reads web pages. According to the Meta commercial terms preview, Meta may access, index, cache and collect domains, web pages and URLs related to your products and services. If you run Meta ads, read the terms and check your robots.txt before the effective date.
What changed The commercial terms now say Meta can read websites linked to a business account with automated tools and use the content for product development, improvement and research. The effective date is October 30.
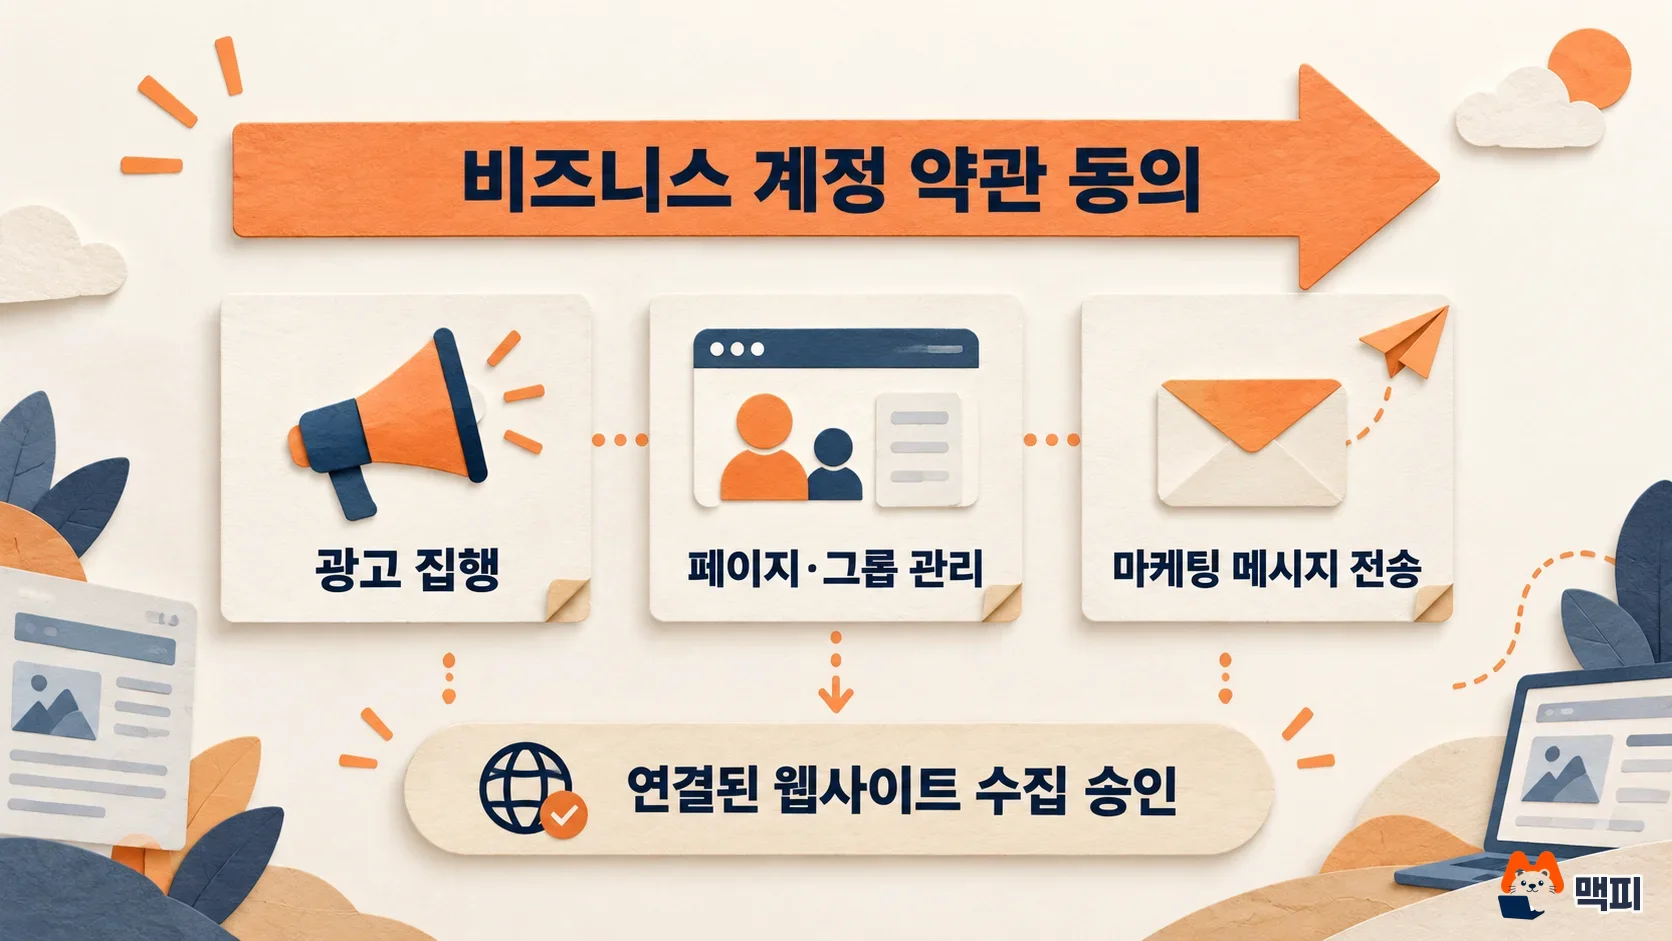
Who is affected Advertisers and operators who use Meta business features such as Ads Manager, Pages and groups, and marketing messages. These terms apply to the use of business tools.
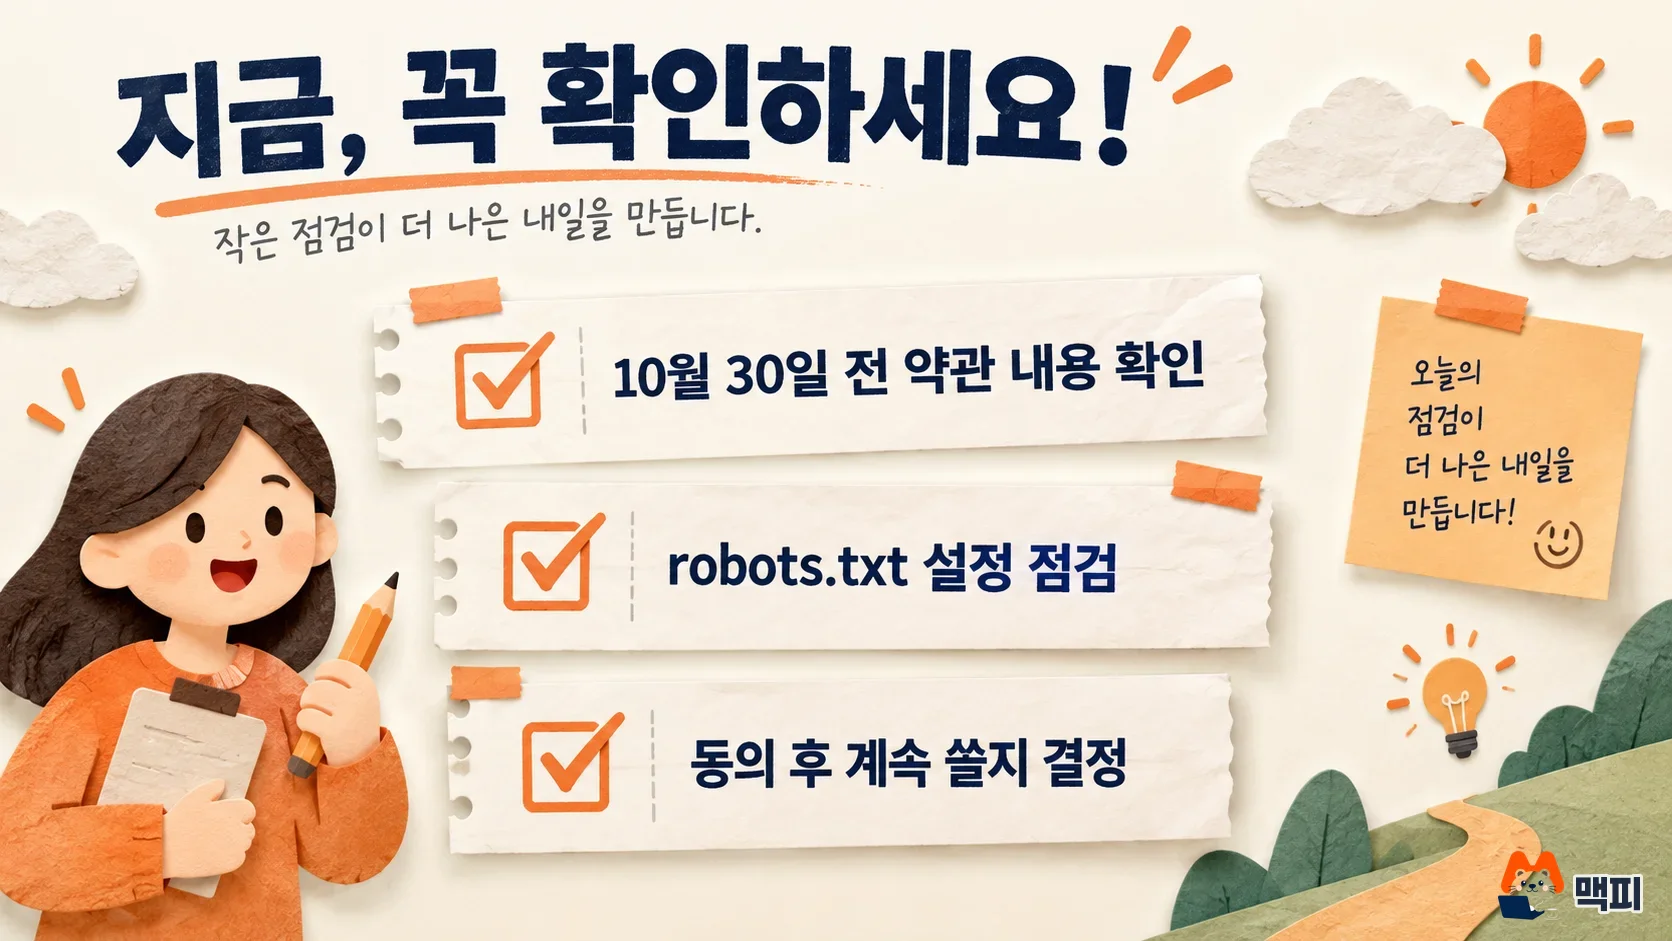
What to do now Read the terms preview, decide in your site's robots.txt whether to allow Meta crawlers, then decide whether to accept the terms and keep using Meta business tools.
What changed in Meta's commercial terms
The preview document has an effective date of October 30, 2026. The clause says you authorize Meta, or parties acting on its behalf, to access those pages with automated software such as web scrapers, bots and crawlers, to create test credentials, and to fetch updates periodically. It states that the collected content can be used to provide, develop and improve products and services, and for research.
At the same time, Meta announced in its business help page that it is simplifying the commerce terms, product catalog terms, self-serve advertising terms and ad creative generative AI terms. According to Nieman Lab's report, Meta said it moved crawling language that was spread across several terms into one place.
In the same report, legal experts said the clause could serve as a basis for collecting content from publishers such as news sites. Meta said its crawling methods are not changing and that you can manage access through robots.txt. Experts argued, however, that the terms could be used to override blocking signals such as robots.txt.
| Item | Details |
|---|---|
| Effective date | October 30, 2026 |
| What is collected | Domains, web pages and URLs related to your products and services |
| How it is collected | Scrapers, bots, crawlers, test credentials, periodic updates |
| Purpose | Providing, developing and improving products and services, research, integrity |
| If you do not agree | Stop using Meta products for business purposes |
Does this apply to my site? Check your business account
According to the Nieman Lab report, the terms apply to features you use through a business account. These include running ads, managing Pages and groups, sending marketing messages and using business account dashboards. If you have connected a store or landing page domain to Meta Ads Manager, it may fall under the phrase "domains related to your products and services." Have the person in charge compare it against the wording of the terms.
The report says there is no way to reject only this clause. The terms preview states that continued use after notice of a revision counts as agreement, and that if you do not agree, you can stop using the products for business purposes.
How to block Meta crawlers: robots.txt setup
According to the Meta developer documentation, Meta crawlers are split by purpose, and most can be blocked with a Disallow rule in robots.txt. The crawler used to train foundation AI models is meta-externalagent. Meta AI search quality uses meta-webindexer, and improving ad and business products uses meta-externalads. If you also block facebookexternalhit, which builds link share previews, link thumbnails may not display properly on Facebook and Instagram.
User-agent: meta-externalagent
Disallow: /

User-agent: meta-webindexer
Disallow: /

User-agent: meta-externalads
Disallow: /
Crawlers cache robots.txt for up to 24 hours, so a change can take time to apply. The same document says meta-externalfetcher and facebookexternalhit may bypass robots.txt. To block them reliably, restrict access on your server by IP or User-Agent. meta-externalads is used to improve ad and business products, so after blocking it, run a small test ad to confirm that ad approval and delivery are not affected.
What to do now: checklist before October 30
- Read the crawling clause in the terms preview and share it with legal and your agency.
- Open your site address followed by /robots.txt and see whether any Meta crawler rules already exist.
- Choose which crawlers to block and add Disallow rules. Keep in mind that meta-externalfetcher and facebookexternalhit may bypass the rules.
- After 24 hours, check your server access logs to see whether requests with the meta-externalagent User-Agent have dropped.
curl -s https://내도메인.com/robots.txt | grep -i -A1 "meta-"
grep -ci "meta-externalagent" /var/log/nginx/access.log
The first command checks that the Meta crawler rules are actually live in robots.txt. The second counts how many requests from this crawler remain in your access log (the log path differs by server). If requests keep growing more than 24 hours after you add the rules, recheck the rule format.
Sites with paid content or members-only pages should raise the priority. Meta did not answer whether test credentials could bypass access restrictions. Running ads depends on whether you accept the terms. If allowing crawling is difficult, also consider separating the domains you use with Meta ads.
What to watch next
Check the Meta business help page to see whether Meta clarifies, before the effective date, how robots.txt ranks against the terms and how far test credentials can reach.
Frequently asked questions
Can I keep running ads if I do not agree to the Meta terms?
The terms say that if you do not agree, you can stop using the products for business purposes. No way to reject only this clause has been confirmed.
Will blocking in robots.txt also remove Facebook link previews?
Link previews are built by facebookexternalhit, so blocking only meta-externalagent has no effect on them. If you also block facebookexternalhit, the thumbnail and title may not appear.
Found this useful? Share it
Latest posts
Kakao Share Thumbnail Not Showing? Here's the Fix (JavaScript SDK 2025)
Learn why Kakao Share thumbnails don't appear even with a valid imageUrl, and fix it using scrapImage to convert your URL into a KAGE CDN URL. Step-by-step guide.
How to Generate CRM User Manuals in 20 Minutes with Claude Code Sub-Agents
Learn how Claude Code sub-agents can analyze your CRM codebase and auto-generate user manuals and visual guidebooks in just 20 minutes. See the real-world results.
GEO Generative Engine Optimization: The Complete 2025 AI Marketing Strategy Guide
Learn what GEO (Generative Engine Optimization) is, how it differs from traditional SEO, and discover 5 proven AI marketing strategies to get cited by AI search engines in 2025.
Related projects
Get new posts by email
Insights on marketing, analytics, and dev, delivered to your inbox.