Gemini Interactions API tool search preview: only apps with many tools save tokens
Tool retrieval in the Gemini API does not send every tool definition with each request. The model searches for tools and loads them when it needs them. In its Nov 19, 2026 changelog, Google said it was added to the Gemini Interactions API as a preview. An app with dozens of tools that uses only a few per request can cut input tokens a lot. An app with about 10 tools and long conversations may see tokens go up instead, so run the numbers before you turn it on.
On Nov 19, 2026, tool search, which loads tool definitions only when needed, arrived in preview in the Gemini Interactions API.
There is no extra charge. It follows the model's standard input and output pricing. In Google's documentation example, an app with 200 tools drops from about 164,000 to 23,650 input tokens, but an app with 10 tools and a long conversation rises from 68,000 to 92,830.
It does not work with generateContent. It is only for the v1beta Interactions API. According to the docs, the supported models are gemini-4-hydrogen, gemini-4-argon, gemini-3.8-flash and gemini-3.6-flash.
Static loading, server search or client search: which should you pick
Google's tool retrieval docs describe three ways to give tools to the model in the Gemini Interactions API. Until now, static loading was the default. It sends every tool definition with every request.
| Item | Static loading | Server search | Client search |
|---|---|---|---|
| How tools reach the model | All sent with every request | Gemini loads deferred tools when needed | Your app returns tools when needed |
| Search code you write | None | None | Search, ranking and filter logic |
| Extra round trips per search | None | None (handled inside one API call) | One |
| Best for | A stable set of fewer than about 20 tools | A large but fixed tool list | Your own tool registry, per-user tool sets |
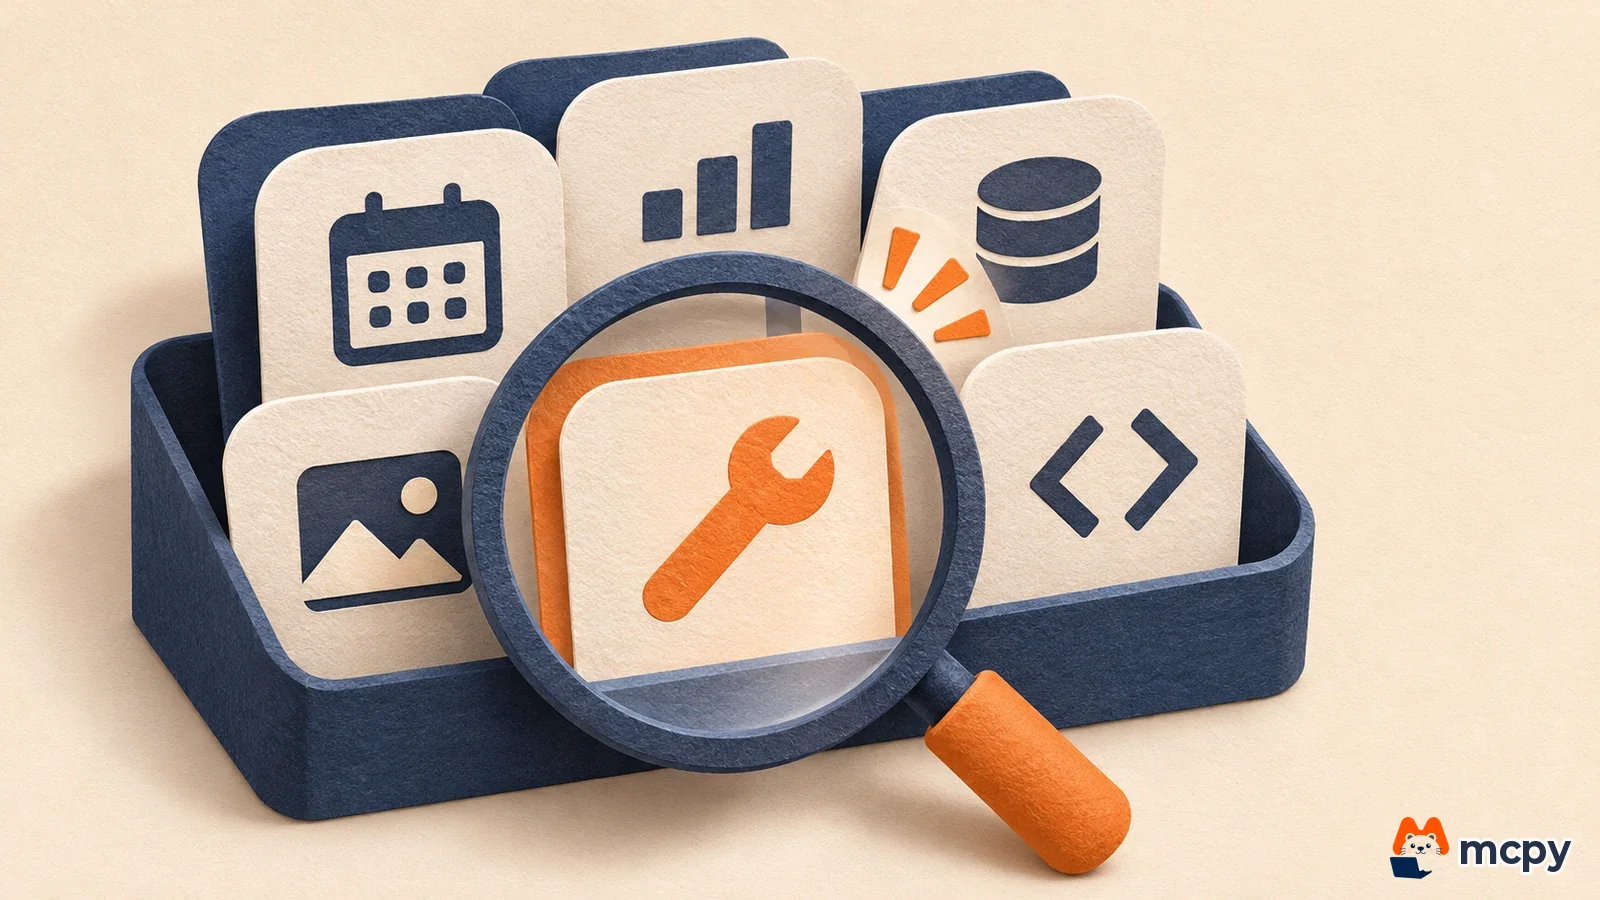
Figure 1 is the original comparison table from the docs. Server search is the default, so it is the simplest to set up. Client search fits setups where a user adds a new integration and tools get added mid-conversation. The docs say static loading suits a stable set of fewer than about 20 tools, so if you are below that size, you can keep your current approach. Source: Google Gemini API docs capture (Nov 20, 2026).
Gemini Interactions API tool search setup steps and how to verify
For server search, add one {"type": "tool_search"} entry to the tools array and add defer_loading: true to each function you want to defer. The docs explain that adding it to an mcp_server entry defers all tools from that server. The model sees only the name and description of deferred tools. When it needs one, it emits a search step and the API returns the full schema.
from google import genai

client = genai.Client(http_options={"api_version": "v1beta"})
tools = [
    {"type": "tool_search"},
    {"type": "function", "name": "convert_currency",
     "description": "Convert an amount between currencies.",
     "defer_loading": True,
     "parameters": {"type": "object",
       "properties": {"amount": {"type": "number"}, "to": {"type": "string"}},
       "required": ["amount", "to"]}},
]
interaction = client.interactions.create(
    model="gemini-4-hydrogen",
    input="Convert 100 USD to EUR.",
    tools=tools,
)
for step in interaction.steps:
    print(step.type, getattr(step, "name", ""))
The code above is a shortened version of Google's docs example. When it works, steps first shows a search step and a search result step, then a function_call. The search step is handled inside a single API call, so your code does not need to respond to it. You only run the function_call and return it as a function_result. The docs advise you not to rely on the status value and to check whether a function_call step exists.
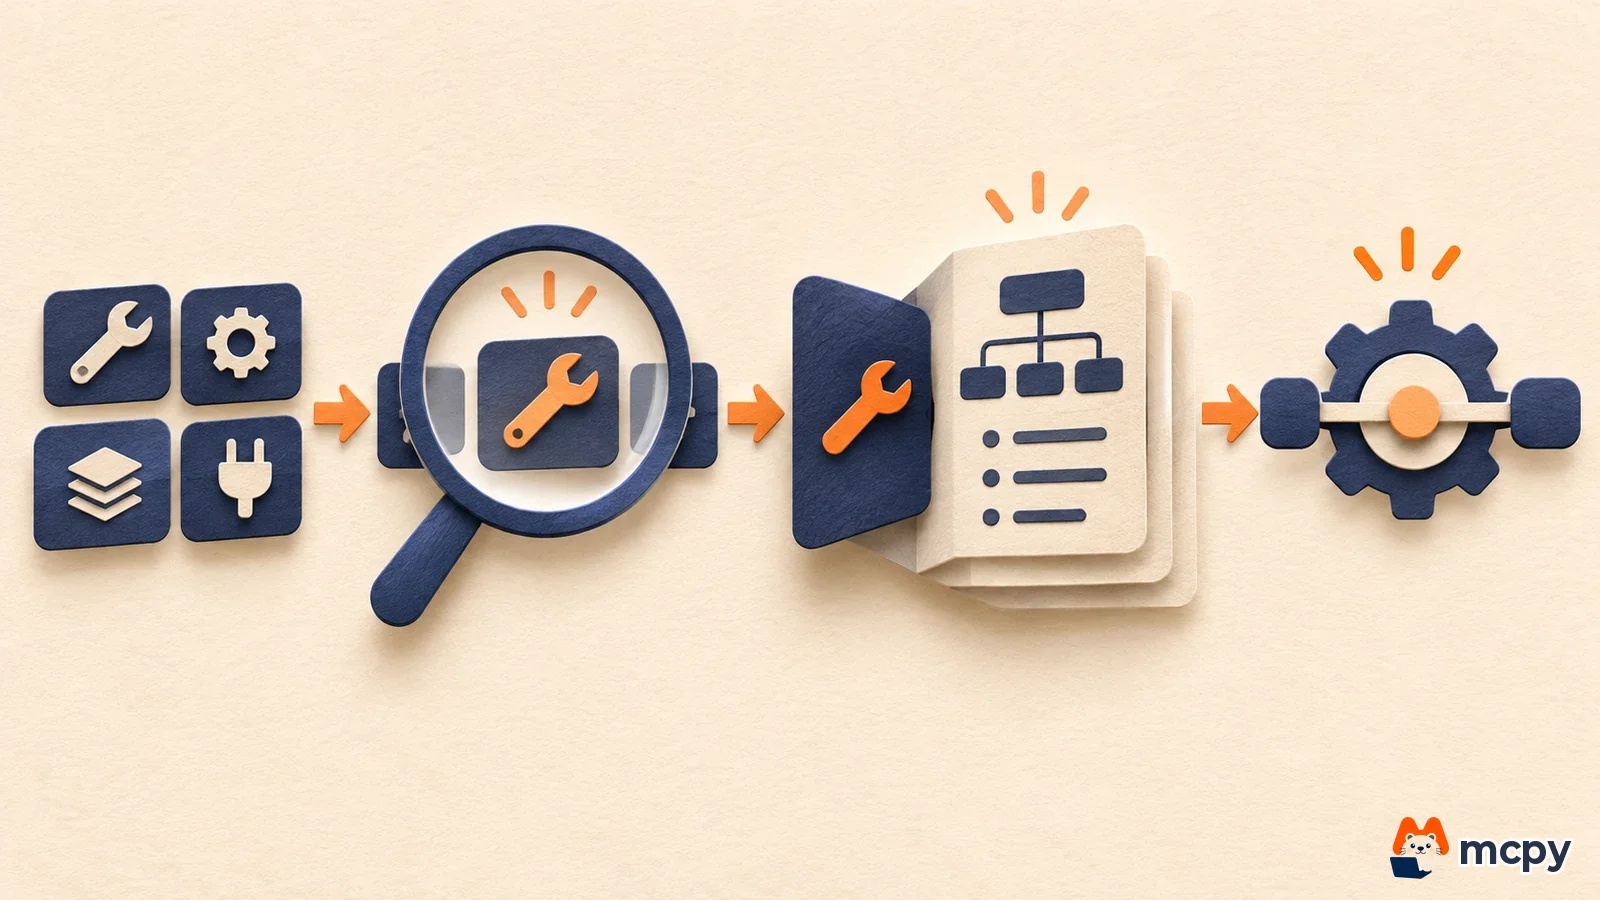
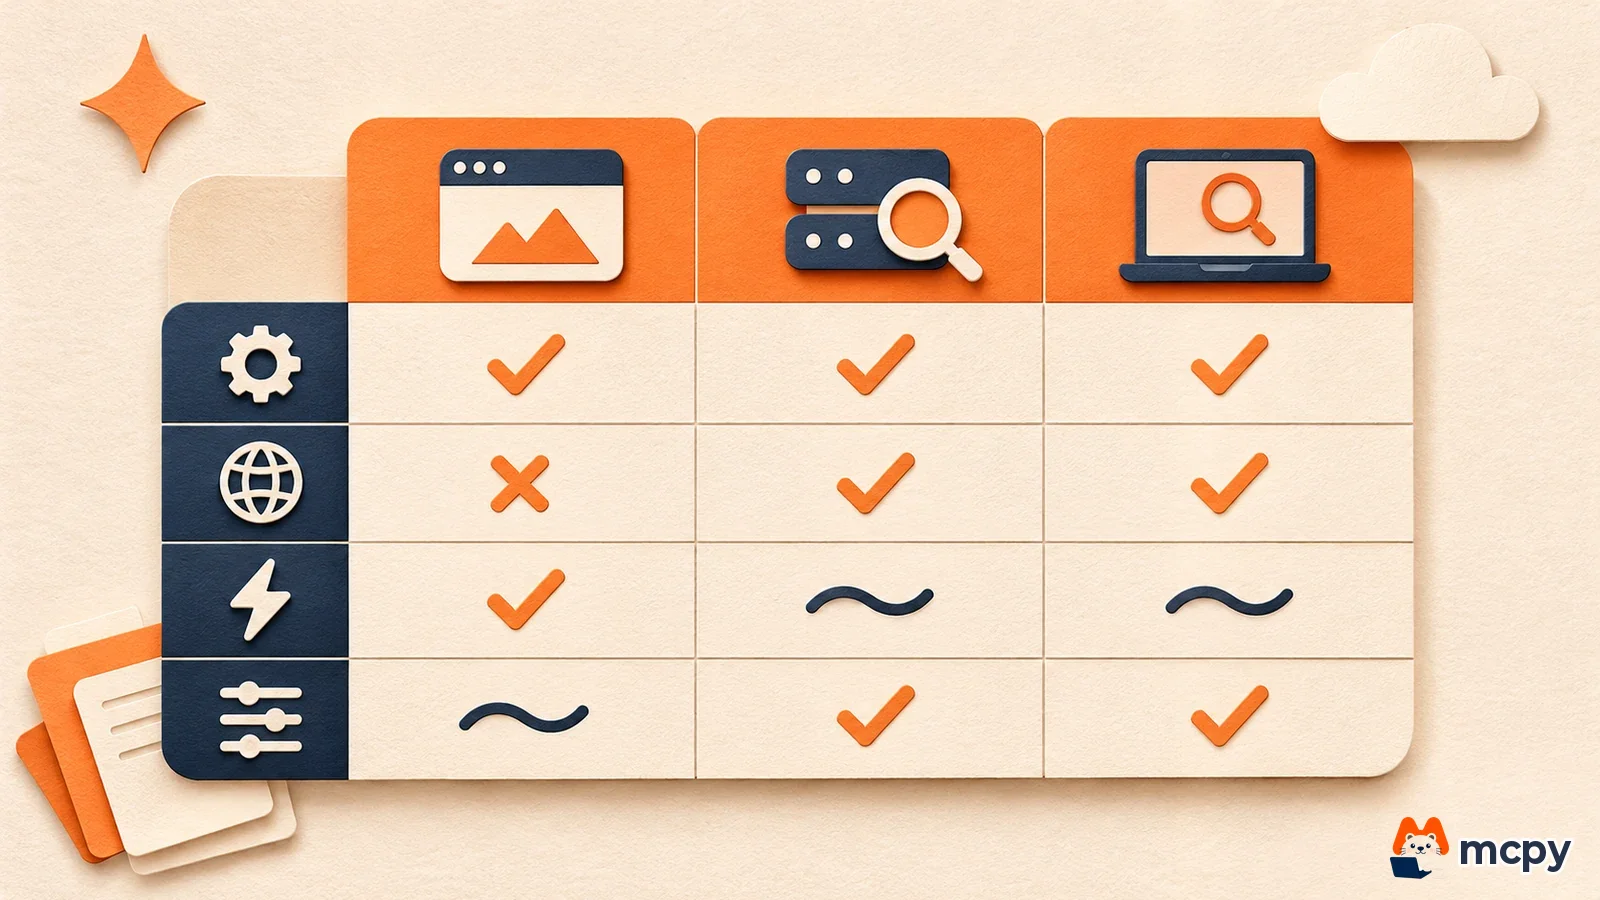
Figure 2 shows the order in which a request runs. Google's docs advise you to measure with your own traffic before you turn it on broadly. Send a static loading request and a tool search request separately to the same model, then compare total_tool_use_tokens and input tokens in the responses to see if it pays off. This comparison method is Mcpy's suggestion, adapted from the docs example.
Why you must resend the tools array every request, and the 400 errors
Tool declarations are not saved between requests. According to the tool retrieval docs, even with previous_interaction_id you must resend the tool_search entry, the deferred tools and the non-deferred tools every time. If you skip them, the model may keep trying to call earlier tools. If you manage state yourself with store=false, you must send the search call and result steps back in order, including the signature. You can read the background on the changed storage default in our post on the Gemini API request storage default.
| Error message | How to fix it |
|---|---|
| tool_search tool must be specified when using defer_loading. | Add the tool_search entry or remove defer_loading |
| Cannot specify both client-side and server-side tool_search tools. | Declare only one type |
| deferred loading is not supported for this model | Switch to a supported model |
| short_description can only be set if defer_loading is true | Turn on defer_loading or remove short_description |
| Server side tool call context must be circulated when using deferred loading functions. | In a stateless flow, resend the missing search steps as they were |
| Tool call part is missing thought_signature. | Restore the signature that was dropped from the search step |
Which apps save tokens and which apps use more
In the billing section of the tool retrieval docs, Google says it applies the model's standard input, cache and output rates with no separate charge. However, each deferred tool adds one line with its name and short description to the input, about 26 tokens per tool in early testing. Each time a server search happens, one more model call runs inside the same request. It includes the full conversation plus the loaded schemas, and that whole prompt is counted as total_tool_use_tokens. Loaded schemas stay until the conversation ends and count as input in later calls. There is no way to unload a tool once it is loaded.
Here is the math behind Figure 3. In the 200-tool example, the first request is 7,350: a 2,000-token conversation, a 5,200-token deferred list (200 x 26) and 150 tokens of instructions. The search call adds 8,150, and the second request is 8,150, for about 23,650. In the 10-tool example, the conversation is 30,000 tokens, so the search call sends that conversation once more. That makes about 92,830, more than the 68,000 of static loading. Both examples are illustrative calculations built from numbers Google rounded, not measurements, and they leave out output tokens and caching. Source: Google Gemini API docs capture (Nov 20, 2026).
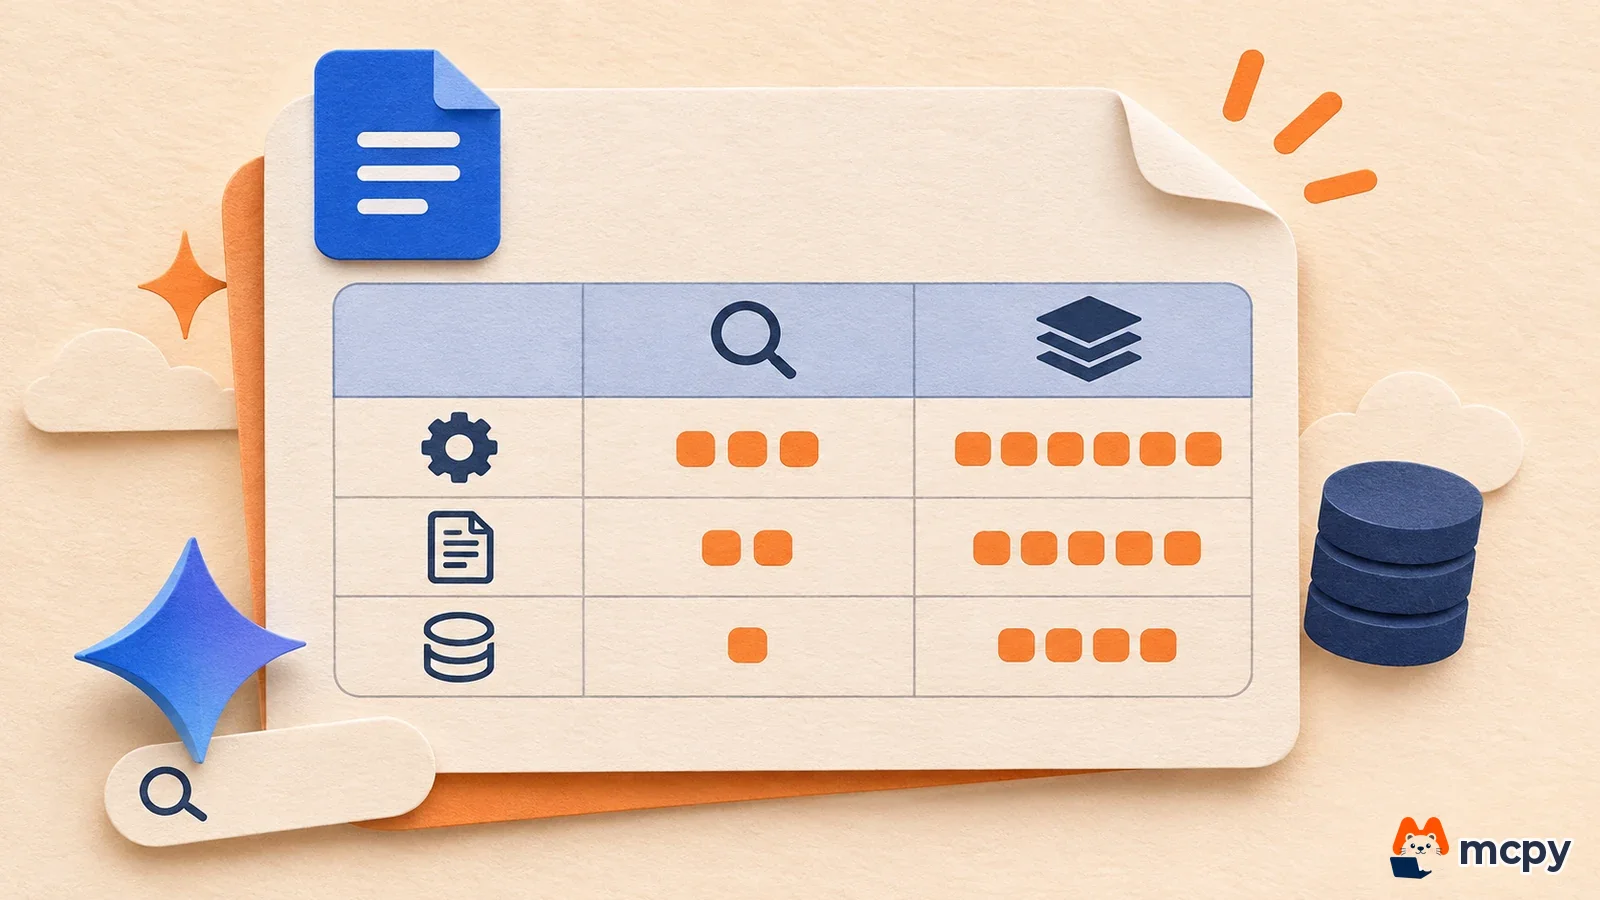
Summing up Google's explanation of when it saves, it pays off for apps where tool definitions take a big share and most requests search zero or one time. It is the opposite for apps with few tools or long conversations where almost every request searches. Deferring tools can also make the prompt smaller than the model's minimum cache size.
Reading it vertically, the deferred list and the search call make up most of the input. The 2 loaded schemas (800 tokens) are a small share, and as you add tools the list grows by only about 26 tokens per tool.
Limits to know before you use it and design tips
According to the limits list in the tool retrieval docs, tool search works only in the v1beta Interactions API and is not supported in generateContent. You cannot mix server search and client search in one request, and defer_loading is for server search only. If no search result matches, the answer comes back as text instead of a structured error, so do not judge a failed search from the search result step alone. The docs also say the API shape may change before general release.
Model support is worded a little differently in the supported models section of the docs and in the changelog. The changelog says Gemini 3.6 and later models, including all of Gemini 4. The tool retrieval docs list four models: gemini-4-hydrogen, gemini-4-argon, gemini-3.8-flash and gemini-3.6-flash. Using defer_loading on an unsupported model returns a 400 error, so check that your model is on the list first. Hydrogen pricing and the free tier are in our Gemini 4 Hydrogen general availability post, and the 3.8 Flash replacement schedule is in our summary of Gemini API model changes.
The design advice in the docs is to defer only the long tail and not the tools you use often. Do not defer tools you call directly by name, and include the full parameter schema even for deferred functions. If you send only a name and short description, search returns an empty schema and the model cannot call it. Prefix similar function names with the service name, and write in the system instruction when to search.
Claude and GPT have this feature too
Anthropic offers a same-named tool search tool as stable. It supports two search methods, regex and BM25, and up to 10,000 deferred tools per request. OpenAI also has tool_search and defer_loading, and its docs say the Responses API supports only gpt-5.4 and later models. The same idea exists at all three companies, but the implementations differ.
| Item | Gemini API | Claude API | OpenAI API |
|---|---|---|---|
| Search tool name | tool_search | tool_search_tool_regex_20251119, tool_search_tool_bm25_20251119 | tool_search |
| Usable API | Interactions API only (v1beta, preview) | Messages API and others (stable) | Responses API |
| Supported models | gemini-4-hydrogen, gemini-4-argon, gemini-3.8-flash, gemini-3.6-flash | Current models from Claude Opus 4.5 onward (Opus 4.1 and earlier excluded) | gpt-5.4 and later models |
| How to defer | defer_loading on functions and mcp_server entries | defer_loading in tool definitions, mcp_toolset setting for MCP | defer_loading on functions and MCP server tools, namespaces supported |
| Separate charge | None, standard model pricing | No separate server tool charge, loaded definitions count as input tokens | No pricing mentioned in the docs |
The criteria for deciding whether you need tool search are similar. The Claude docs recommend it when you have 10 or more tools or definitions exceed 10,000 tokens, which differs from the Gemini docs' threshold of about 20 tools. But each doc's threshold comes from different models and calculations, so do not compare the numbers directly. It is better to measure your own app's definition token count and decide from that.
Frequently asked questions
Does tool search cost extra?
Google's docs say there is no separate charge and the model's input, cache and output rates apply as is. However, each search triggers one more model call, so input tokens can go up.
Can I defer MCP server tools too?
If you add defer_loading to a remote mcp_server entry, all tools the server exposes are deferred. The docs say this is useful when several servers have many tools.
Can I use it in an app built with generateContent?
No. Tool search is only for the Interactions API, so to use it in an existing app you must first move to the Interactions API.
Found this useful? Share it
Latest posts
Kakao Share Thumbnail Not Showing? Here's the Fix (JavaScript SDK 2025)
Learn why Kakao Share thumbnails don't appear even with a valid imageUrl, and fix it using scrapImage to convert your URL into a KAGE CDN URL. Step-by-step guide.
How to Generate CRM User Manuals in 20 Minutes with Claude Code Sub-Agents
Learn how Claude Code sub-agents can analyze your CRM codebase and auto-generate user manuals and visual guidebooks in just 20 minutes. See the real-world results.
GEO Generative Engine Optimization: The Complete 2025 AI Marketing Strategy Guide
Learn what GEO (Generative Engine Optimization) is, how it differs from traditional SEO, and discover 5 proven AI marketing strategies to get cited by AI search engines in 2025.
Related projects
Get new posts by email
Insights on marketing, analytics, and dev, delivered to your inbox.